OCR REST API
API references
- ABBYY FREngine11 user guide attached OCR API
- ABBYY user guide with short examples: OCR API Part I and OCR API Part II
Authentication
Like some other components of IA Cloud Enterprise, Optical Character Recognition (OCR) uses JWT for authentication. To access most OCR resources, you need to retrieve the JWT token. For that, you can access any Workfusion instance, provide a user login/password and retrieve a short-living JWT token:
curl -X POST -H Content-Type:application/json -d '{"username":"'","password":""}' http:///workfusion/api/v1/jwt/login
You can use that token in the HTTP Authorization header:
Authorization:Bearer
Using command line
Process image: specifies an appropriate location of a file (FILENAME) and OCR parameters to processImage API call.
curl -s --form "file=@FILENAME" "http://ocr.hostname:8080/api/v1/cloud/processImage?correctSkew=true&xml:writeRecognitionVariants=false&profile=documentConversion&exportFormat=txt&language=English&correctOrientation=true"Output: copies a task ID for the next command.
<?xml version="1.0" encoding="UTF-8" standalone="yes"?><response><task id="5693d8f77b78005fcbbfbe84" message="OK" processEndTime="2016-01-11T16:32:00" processStartTime="2016-01-11T16:31:56" registrationTime="2016-01-11T16:32:28" resultUrl="http://ocr.hostname:8080/api/v1/cloud/download?taskId=5693d8f77b78005fcbbfbe84&result=1" resultUrl2="http://ocr.hostname:8080/api/v1/cloud/download?taskId=5693d8f77b78005fcbbfbe84&result=2" resultUrl3="http://ocr.hostname:8080/api/v1/cloud/download?taskId=5693d8f77b78005fcbbfbe84&result=3" statusChangeTime="2016-01-11T16:32:28" status="Completed"/></response>Gets status by the task ID:
curl -s "http://ocr.hostname:8080/api/v1/cloud/getTaskStatus?taskId=5693d8f77b78005fcbbfbe84"Output: If
message="OK", you can download results from links inresultUrl,resultUrl2,resultUrl3(depends on the export format).<?xml version="1.0" encoding="UTF-8" standalone="yes"?><response><task id="5693d8f77b78005fcbbfbe84" message="OK" processEndTime="2016-01-11T16:32:00" processStartTime="2016-01-11T16:31:56" registrationTime="2016-01-11T16:32:28" resultUrl="http://ocr.hostname:8080/api/v1/cloud/download?taskId=5693d8f77b78005fcbbfbe84&result=1" resultUrl2="http://ocr.hostname:8080/api/v1/cloud/download?taskId=5693d8f77b78005fcbbfbe84&result=2" resultUrl3="http://ocr.hostname:8080/api/v1/cloud/download?taskId=5693d8f77b78005fcbbfbe84&result=3" statusChangeTime="2016-01-11T16:32:28" status="Completed"/></response>
API Usage
API sequence call
Uploads file with
submitImage.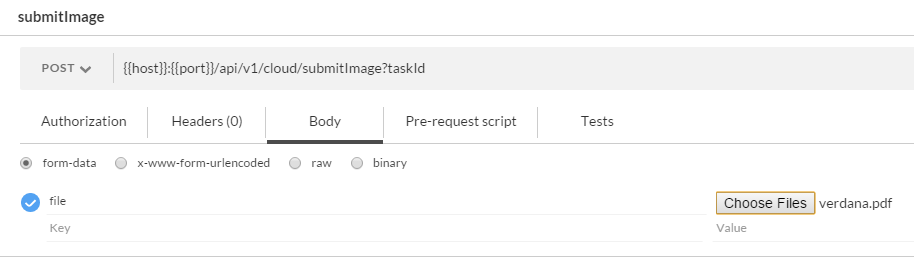
Copies
taskIdfrom the response:<?xml version="1.0" encoding="UTF-8" standalone="yes"?>
<response>
<task id="5b06b1b295ac0b000144fb7e" processEndTime="" processStartTime="" registrationTime="2018-05-24T12:36:02"
resultUrl="http://ocr2-dev2.crowdcomputingsystems.com:8080/api/v1/cloud/download?taskId=5b06b1b295ac0b000144fb7e&
result=1" resultUrl2="http://ocr2-dev2.crowdcomputingsystems.com:8080/api/v1/cloud/download?taskId=5b06b1b295ac0b000144fb7e&
result=2" resultUrl3="http://ocr2-dev2.crowdcomputingsystems.com:8080/api/v1/cloud/download?taskId=5b06b1b295ac0b000144fb7e&
result=3" statusChangeTime="2018-05-24T12:36:02"
status="Submitted"/>
</response>Starts image processing with
processDocument.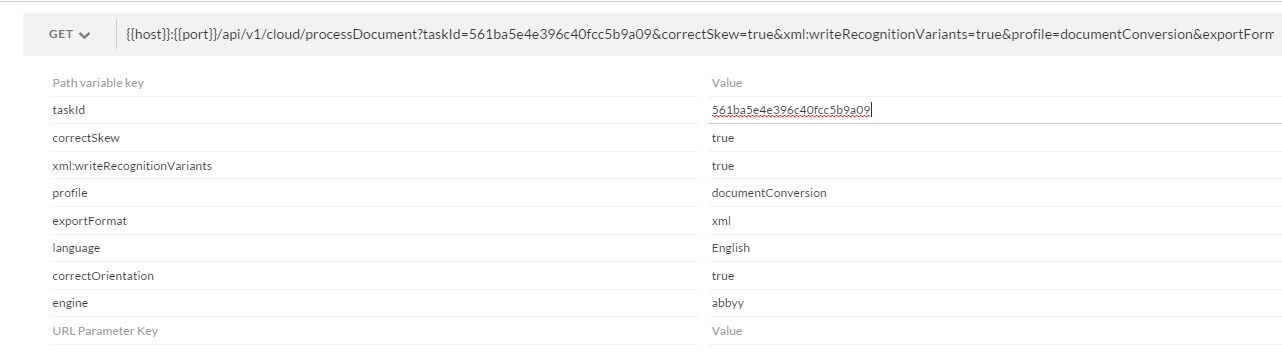
Checks task status with
getTaskStatus(specify correcttaskId).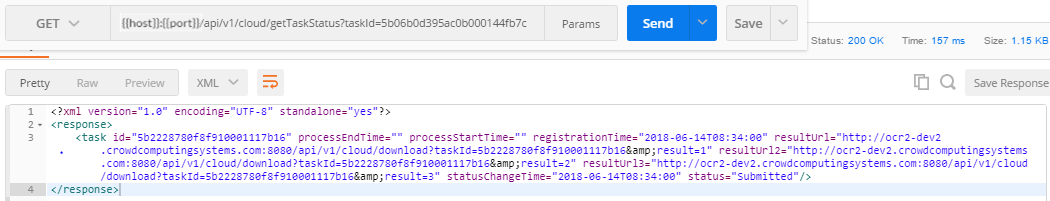
If the task is complete (
status="Completed"), open results from theresultUrl,resultUrl2orresultUrl3fields (replace&with&).
Custom request parameters
We implement custom or additional request parameters. See the following sections.
GET /cloud/processDocument
exportFormat: OCR API export format:html: HTML pagepdfSearchable: text can be searched in this type of filexml: file contains characters or words along with their location in the original document (coordinates or frames)xmlForCorrectedImage: the same asxml, except location is taken from a processed or adjusted documentxmlWithoutRecognitionVariants: the same asxml, but does not contains character-related datatxt: plain text (default)
For multiple export formats, you can use combinations delimited by a comma:
pdfSearchable,xmlForCorrectedImage,html. You can use maximum of three types at once.customRegions: a JSON variable that defines the area of a special type. The following supported types perform actions within a specified region:BT_Table: table recognitionBT_Barcode: barcode recognitionBT_Checkmark: single checkmark recognition; supports thecheckmarkConfigurationfield with checkmark settingsBT_CheckmarkGroup: group of checkmark recognition; supports thecheckmarkConfigurationfield with checkmark settings; expects theinnerRegionsfield.- One of
BT_RasterPicture,BT_VectorPicture,BT_Separator,BT_SeparatorGroupenables analysis within the specified region in isolation (does not include information from the surrounding context)
[
    {
        "type": "BT_Table",
        "page": 1,
        "left": 0,
        "top": 0,
        "right": 2000,
        "bottom": 2000
    },
    {
        "type": "BT_Table",
        "page": 1,
        "left": 0,
        "top": 2000,
        "right": 4000,
        "bottom": 4000,
    },
    {
        "type": "BT_Table",
        "page": 2,
        "left": 0,
        "top": 0,
        "right": 4000,
        "bottom": 4000
    }
]
The example to select one table region for all pages.
[
    {
        "type": "BT_Table",
        "left": 0,
        "top": 0,
        "right": 2000,
        "bottom": 2000
    }
]correctSkew(default true): if true, the page skew is detected and automatically corrected.correctOrientation(default true) specifies whether the orientation of the image should be automatically detected and corrected. If true, the page orientation is detected. If it differs from normal, it is automatically rotated.skipPreprocessing(default false) disables all pre-processing steps for a document. Parameters that are disabled ifskipPreprocessing=true:convertTo,changeDPI,useAutoDetectedDPIFromRange,removeNoiseModels,removeGarbageSize,removeColorObjectsType,removeColorObjects,correctSkew,invertImage,discardColorImage,enhanceLocalContrast,correctOrientation,lowResolutionMode,useWordsFromDictionaryOnly.useOnlyCustomRegions(default false) skips the original analyzing stage to process custom regions only and extracts information from custom regions only.useWordsFromDictionaryOnlyspecifies if dictionary words are allowed during recognition in this base language only. If true, a word that is not found in the dictionary of the base language can appear in the recognized text only if ABBYY FineReader Engine found no dictionary variants.dictionaryis a word or a combination of characters that can be used to improve OCR recognition. The set of words extends, not limits, the default dictionary.alphabetExtensionis a string with special symbols to extend the already defined alphabet, for example,abc123.customAlphabetis a string with special symbols to extend the already defined alphabet, for example,abc123.useDefaultPattern(default false): if true, it requires applying the default pattern (from the OCR application bundle).removeNoiseModelsremoves noise on the image (optional, valid value - comma-separated values:CorrelatedNoise,WhiteNoise). The method can be used for color and 8-bit gray images only.removeGarbageSizeremoves garbage (excess dots that are smaller than a certain size) from the image (optional, valid value > 0 and -1 for automatic detecting garbage size).skipTextLayerExtraction: a text layer of the source PDF file is not used; the image layer is recognized by ABBYY FineReader Engine.debugturns off cleanup of temporary files once the recognition is finished. Also, turns on FREngine logging.discardColorImage: if you work with black-and-white images or the color of images is not important, setdiscardColorImageto true.enhanceLocalContrastspecifies whether the local contrast of the image should be increased. Such preprocessing may increase the quality of recognition. It is effective for:- photos or scans of documents with texture or pictures in the background
- photos or scans of documents with highly colorful background or text highlighting
languagespecifies a predefined language, for example, English. You can also define multiple languages and use a comma as a separator:English,German,Polish.lowResolutionMode:true.falseimproves recognition of images with low resolution, for example, faxes.textTypespecifies the text type in the document. The parameter may also contain several text types separated with commas, for examplenormal,matrix. The following values can be used:normaltypewritermatrixocrAocrBe13b
infoText type recognition works on the block level by default. It means one paragraph cannot contain a mix of types. To enable recognition per word, use the
textExtractionprofile.
Pre-processing parameters:
invertImage(defaultfalse) inverts image colors.discardColorImage(defaultfalse) leaves only a black-and-white plane in the prepared image.infoThe parameter discards a color plane of a document. Therefore, it is incompatible with the
removeColorObjectsparameter.removeColorObjectsremoves color objects from the image, colors values: Blue, Green, Red, Yellow.infoThe parameter applies color filtering to a color image plane of a document. Therefore, it is incompatible with the
discardColorImageparameter.removeColorObjectsTypespecifies the type of the objects to be removed. Supported types:Full,Background,Stamp.Full: all color objects on the imageBackground(default): color objects on the backgroundStamp: only color stamps and signatures
infoThe method can be used for color images only. You can also use only one type per request.
convertTo(value=TIFF): automatic detection of the file type and conversion to TIFF (convert before processing). Accepts images: PDF, PNG, JPG, JPEG.pages: selection of pages from PDF files for recognition, for example,pages=1,2,3,10-15.changeDPIcontains the new value of DPI. Available values: from 50 to 3,200, for example,changeDPI=300.useAutoDetectedDPIFromRangeselects the best resolution from the specified range and changes the resolution of the image. The range should be in the JSON format, for example,{"min": 50,"max": 3200}.ChangeDPIis not applicable whenuseAutoDetectedDPIFromRangeis defined. When the engine cannot define the best DPI, the original DPI is used.timeoutsets up timeout in seconds between tasks execution.storePreprocessedDocspecifies whether preprocessed documents should be saved into data storage.
POST /cloud/processImage
file: file in one of the following formats: PDF, PNG, JPG, JPEGexportFormat: OCR API export format:html: HTML pagepdfSearchable: text can be searched in such a filexml: file contains characters or words along with their location in the original document (coordinates and frames)xmlForCorrectedImage: the same as XML, except location is taken from a processed or adjusted documenttxt: plain text (default)
For multiple export formats, you can use combinations delimited by the comma:
pdfSearchable,xmlForCorrectedImage,html. You can use maximum of three types at once.xml:writeRecognitionVariantsmakes XML and xmlForCorrectedImage formats to contain all variants of character or word OCR considered as a possible recognition.customRegions(JSON variable) defines the area of a special type. The following supported types perform actions within a specified region:BT_Table: table recognitionBT_Barcode: barcode recognitionBT_Checkmark: single checkmark recognition. Supports thecheckmarkConfigurationfield with checkmark settingsBT_CheckmarkGroup: group of checkmark recognition. Supports thecheckmarkConfigurationfield with checkmark settings. Expects theinnerRegionsfield
detectLanguagespecifies whether FineReader Engine should automatically detect the recognition language of a text. Autodetection is intended to be used during the recognition of documents the language of which is not known to youprofileallows fine-tuning the Engine. Supported profiles:documentConversionfor converting documents into editable formats, optimized for accuracytextExtractionfor extracting text from documents, optimized for accuracybarcodeRecognitionfor extracting barcodes, optimized for accuracy
The settings provided in these profiles are most suitable in the corresponding situations.
correctSkew(default true): if true, the page skew is detected and automatically corrected.correctOrientation(default true): if true, the page orientation is detected. If it differs from normal, it is automatically rotated.skipPreprocessing(default false) disables all pre-processing steps for a document. Parameters that are disabled ifskipPreprocessing=true: convertTo, changeDPI, useAutoDetectedDPIFromRange, removeNoiseModels, removeGarbageSize, removeColorObjectsType, removeColorObjects, correctSkew, invertImage, discardColorImage, enhanceLocalContrast, correctOrientation, lowResolutionMode, useWordsFromDictionaryOnly.customAlphabet: a string with special symbols to extend already defined alphabet, for example,abc123.useWordsFromDictionaryOnly: specifies if only the dictionary words are allowed during recognition in this base language. If true, a word that is not found in the dictionary of the base language can appear in the recognized text only if ABBYY FineReader Engine found no dictionary variants.useOnlyCustomRegions(default false): skips the original analyzing stage and extracts information from custom regions only.alphabetExtension: a string with special symbols to extend an already defined alphabet.useDefaultPattern(default false): if true, it requires applying the default pattern (from the OCR application bundle).dictionary: a file where each line contains a word or combination of characters that can be used to improve OCR recognition. The set of words extends, not limits, the default dictionary.removeNoiseModelsremoves noise on the image (optional, valid value - comma separated values:CorrelatedNoise,WhiteNoise). This method can be used for color and 8-bit gray images only.removeGarbageSizeremoves garbage (excess dots that are smaller than a certain size) from the image (optional, valid value > 0).enhanceLocalContrastspecifies whether the local contrast of the image should be increased. Such preprocessing may increase the quality of recognition. It is effective for:- photos or scans of documents with texture or pictures in the background
- photos or scans of documents with highly colorful background or text highlighting
languagespecifies a predefined language, for example, EnglishlowResolutionModeimproves recognition of images with low resolution, for example, faxes. If true, adapts to low resolution imageskipTextLayerExtractiontext layer of the source PDF file is not used; the image layer is recognized by ABBYY FineReader Enginedebugturns off cleanup of temporary files once the recognition is finished. Also, turns on FREngine logging.textTypespecifies the text type in the document. This parameter may also contain several text types separated with commas, for examplenormal,matrix. The following values can be used:normaltypewritermatrixocrAocrBe13b
infoText type recognition works on the block level by default. It means one paragraph cannot contain a mix of types. To enable recognition per word, you need to use the
textExtractionprofile.
Pre-processing parameters:
invertImage(default false) inverts image colors.discardColorImage(default false) leaves only black-and-white plane in the prepared image.infoThe parameter discards a color plane of Document. Therefore, it is incompatible with the
removeColorObjectsparameter.removeColorObjectsremoves color objects from the image, colors values: Blue, Green, Red, Yellow.removeColorObjectsTypespecifies the type of the objects to be removed. Supported types:Full,Background,Stamp.Full: all color objects on the imageBackground: color objects in the backgroundStamp: only color stamps and signatures.
infoThe method can be used for color images only. Also, you can use only one type per request.
convertTo(value=TIFF): autodetection of the file type and conversion to TIFF (convert before processing). Accepts images: PDF, PNG, JPG, JPEG.pages: selection of pages from PDF files for recognition, for example,pages=1,2,3,10-15.changeDPIcontains the new value of DPI. Available values from 50 to 3200, for example,changeDPI=300.useAutoDetectedDPIFromRangeselects the best resolution from the specified range and changes the image resolution. The range should be in the JSON format, for example,{"min": 50,"max": 3200}.ChangeDPIis not applicable whenuseAutoDetectedDPIFromRangeis defined. When the engine cannot define the best DPI, the original DPI is used.timeout: the maximum allowed timeout (in seconds) for a single task execution by OCR Worker. Timeout starts to count down when OCR Worker starts task execution. If task execution exceeded the given timeout, the task is forcibly killed.storePreprocessedDocspecifies whether preprocessed documents should be saved into data storage.
Custom APIs
GET /cloud/summary
Returns the total number of tasks with status.
Sample response:
        Total tasks SUBMITTED
        0


        Total tasks QUEUED
        0


        Total tasks SCHEDULED
        0


        Total tasks INPROGRESS
        0


        Total tasks COMPLETED
        1124


        Total tasks PROCESSINGFAILED
        283


        Total tasks DELETED
        0


        Total tasks CANCELLED
        28
Example value:
<?xml version="1.0" encoding="UTF-8"?>
<MultipleTaskInfo>
  <taskInfoList>
    <message>string</message>
    <tasksCount>0</tasksCount>
  </taskInfoList>
</MultipleTaskInfo>
GET /cloud/cancelTasks
Cancels all tasks with the status SUBMITTED, QUEUED, and INPROGRESS. Returns the number of cancelled tasks for each status group.
Example value:
<?xml version="1.0" encoding="UTF-8"?>
<MultipleTaskInfo>
  <taskInfoList>
    <message>string</message>
    <tasksCount>0</tasksCount>
  </taskInfoList>
</MultipleTaskInfo>
Add the new parameter that defines which tasks to cancel. For example, the upload date or task ID.
POST /cloud/trainPattern
Trains a user pattern for the symbol.
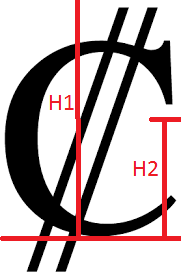
file: image file with a symbolbaseLinecontains the distance from the base line to the top edge of the cropped image of the character. The base line is the line on which the characters are located.- The top edge of the image is determined by the character orientation. H1 on the picture.
smallSymbolHeightspecifies the height of small characters in pixels on the source image. H2 on the picture.symbol: symbol associated with pictures.mergePattern: pattern uploaded as a file. If provided, the training output pattern will be combined with the uploaded.
Request example:
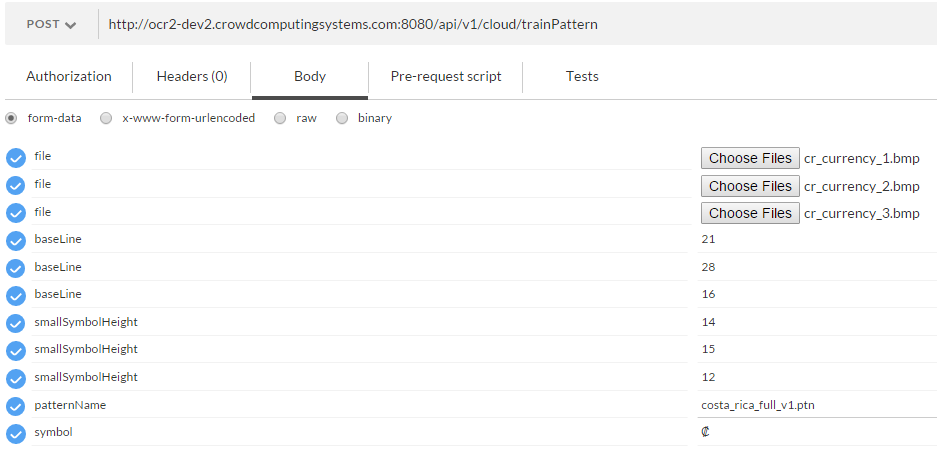
Response is a downloadable pattern file in a proprietary binary format.
Example value:
<?xml version="1.0" encoding="UTF-8"?>
<Error>
  <message>
    <content>string</content>
  </message>
</Error>
When using a custom pattern, you need to specify alphabetExtension with the trained symbol in processImage or processDocument.
POST /submitPattern
The method attaches a pattern file for recognition of special symbols to an existing task created with submitImage. To be consequently processed with the processDocument action.
Parameters:
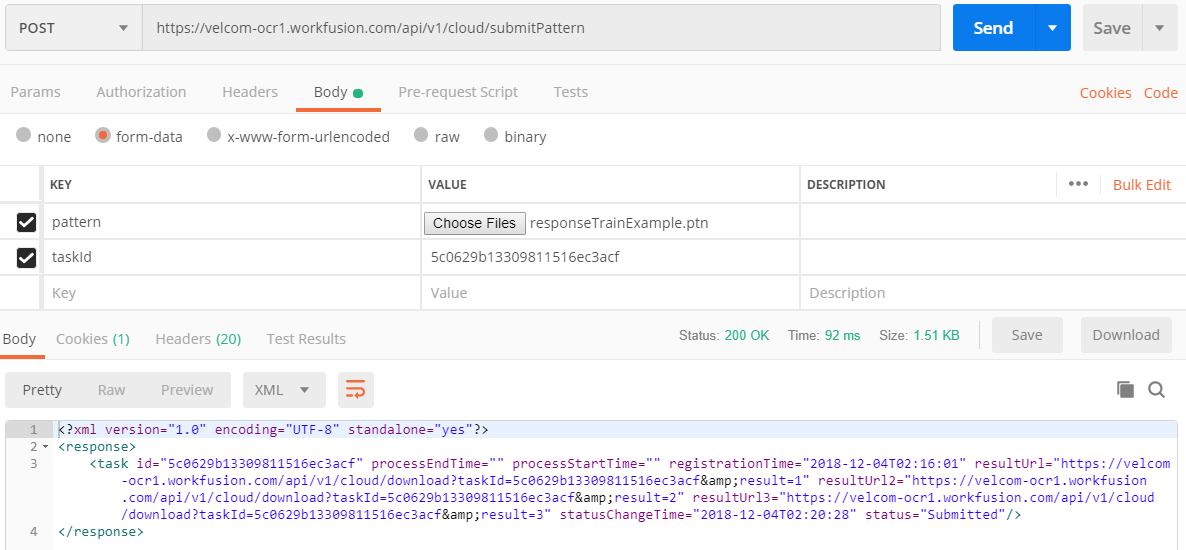
pattern: the pattern file to uploadtaskId: mandatory
GET /project-info
Returns information about the OCR version.
{
  "branch": "string",
  "buildDate": "string",
  "revision": "string",
  "tags": "string",
  "version": "string"
}
GET /health-check
The Health Check endpoint returns information about the health of OCR components.
{
  "components": [
    null
  ],
  "errorCount": 0,
  "errors": [
    "string"
  ],
  "infos": [
    "string"
  ],
  "name": "string",
  "projectInfo": {
    "branch": "string",
    "buildDate": "string",
    "revision": "string",
    "tags": "string",
    "version": "string"
  },
  "status": "OK",
  "warningCount": 0,
  "warnings": [
    "string"
  ]
}
GET /cloud/activeLicense
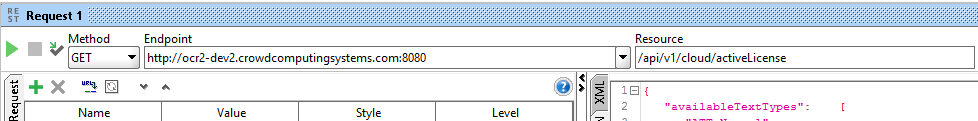
Returns the current active license and all available information about this license.
Result example
{
  "allowedCoresCount": 0,
  "availableBarcodeModules": [
    "string"
  ],
  "availableEngineModules": [
    "string"
  ],
  "availableExportFormats": [
    "string"
  ],
  "availableLanguageSets": [
    "string"
  ],
  "availableTextTypes": [
    "string"
  ],
  "availableVisualComponents": [
    "string"
  ],
  "category": "string",
  "expirationDate": "string",
  "limited": true,
  "minimumCoresCountPerInstance": 0,
  "serialNumber": "string",
  "volume": 0,
  "volumeRefreshingPeriod": "string",
  "volumeRemaining": 0,
  "warnings": [
    "string"
  ]
}
The meaning of the fields in the response:
| Attribute | Explanation |
|---|---|
availableTextTypes | Set of the text types available in the license |
availableBarcodeModules | Set of the ABBYY FineReader Engine barcode modules available in the license |
availableEngineModules | Set of the ABBYY FineReader Engine modules available in the license |
availableExportFormats | Set of the export formats available in the license |
availableVisualComponents | Set of visual components available in the license |
availableLanguageSets | Set of the language sets available in the license |
volumeRefreshingPeriod | Information about the limitation period if the license limits the number of processed pages or characters during this period |
volume | Total number of pages or characters that can be processed during a period if the license has such a limitation |
volumeRemaining | Remaining number of pages or characters that can be processed till the end of the current period if the license has such a limitation. When this property value reaches 0, analysis, recognition and export operations will not be possible. |
serialNumber | Serial number of the license |
allowedCoresCount | Number of CPU cores that can be used simultaneously. If the value of this property is 0, the number of CPU cores is unlimited. |
minimumCoresCountPerInstance | Minimum number of CPU cores which is allocated by ABBYY FineReader Engine at initialization |
GET /cloud/listLicenses
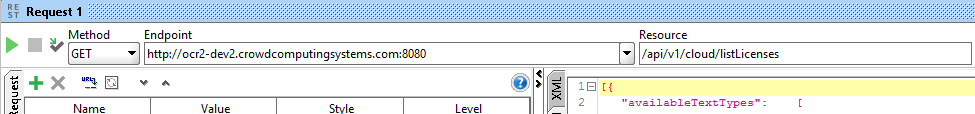
Returns a list of all licenses connected to the current ABBYY Engine.
List of licenses
[
  {
    "allowedCoresCount": 0,
    "availableBarcodeModules": [
      "string"
    ],
    "availableEngineModules": [
      "string"
    ],
    "availableExportFormats": [
      "string"
    ],
    "availableLanguageSets": [
      "string"
    ],
    "availableTextTypes": [
      "string"
    ],
    "availableVisualComponents": [
      "string"
    ],
    "category": "string",
    "expirationDate": "string",
    "limited": true,
    "minimumCoresCountPerInstance": 0,
    "serialNumber": "string",
    "volume": 0,
    "volumeRefreshingPeriod": "string",
    "volumeRemaining": 0,
    "warnings": [
      "string"
    ]
  }
]
POST /cloud/prepareLicense
Generates an input for a license request.
Example value:
"string"
POST /cloud/activateLicense
Activates a license. For activation, you need to have a file with the license.
Example value:
{
  "message": {
    "content": "string"
  }
}
GET /metrics/count
Gets a task count with the status.
Request example:
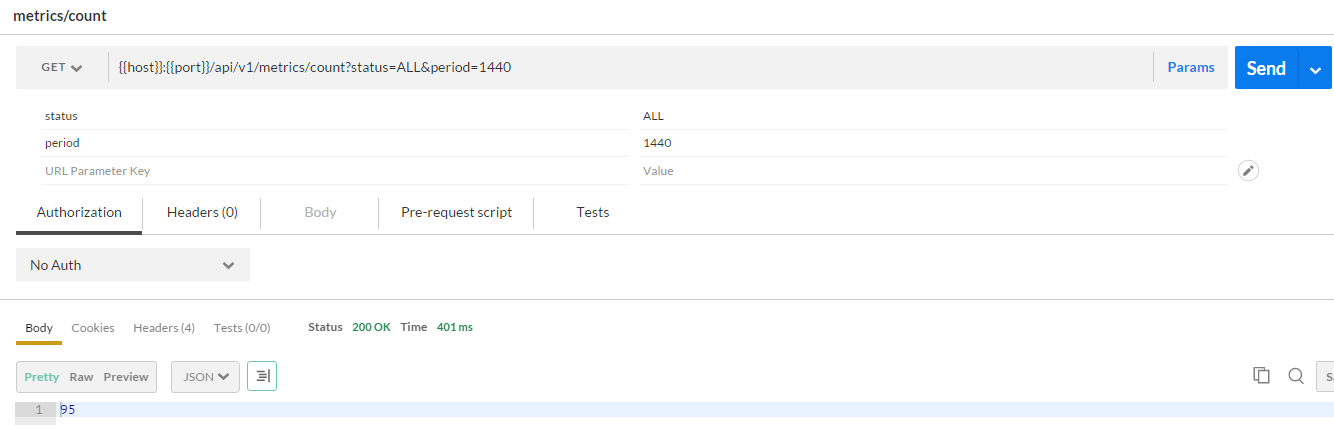
The parameters are as follows:
status: either one ofTaskStatusvalues or aggregate:DONE,PROCESSING,ALLperiod: number of minutes to subtract from the current time. By default, the range isNOW-MINUTEStoNOW. When the period is negative, the range isBEGINNINGtoNOW-MINUTES. The default is 60 minutes.
GET /metrics/stats
Request example:
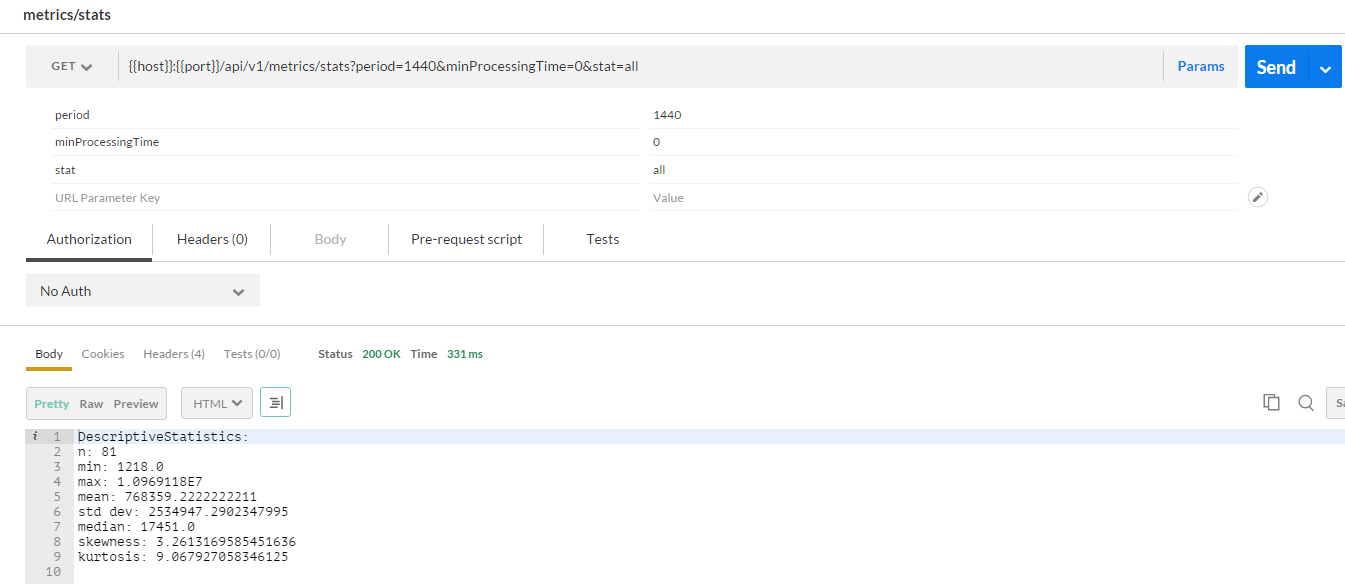
The parameters are as follows:
period: number of minutes to subtract from the current time. By default, the range isNOW-MINUTEStoNOW. The default is 60 minutes.minProcessingTime: tasks with processing time less than this value is discurded. The default is 1,000 (1 second).stat: descriptive statistic:min,max,n(number of values),std,percentileN(where N is any number 0-100), or all.
Multi-worker processing
When process starting to work with specific task it changes task status, so other processes can't also start working with that task thus one task can be processed only by one process-worker.
When server during task processing is terminated we not able to send that task to the queue immediately, but we have service that runs on a schedule and puts such tasks to the queue.
Server specification and usage guidance
Currently, it's a low-parameters instance. Don't submit many documents. License allows only 10K pages to be recognized.
How to use OCR API
OCR is a technology for converting document images into editable text.
There is ability to recognize document by several ways:
- via processImage API
- via processDocument API
An example of picture recognition by several ways is provided below.
Recognition via processImage API
Authentication should be set if needed
POST host:port/api/v1/cloud/processImage
Start image processing with processImage.
- Upload a document or an image as a file.
- Add parameters for correct recognition.
- Send a request.
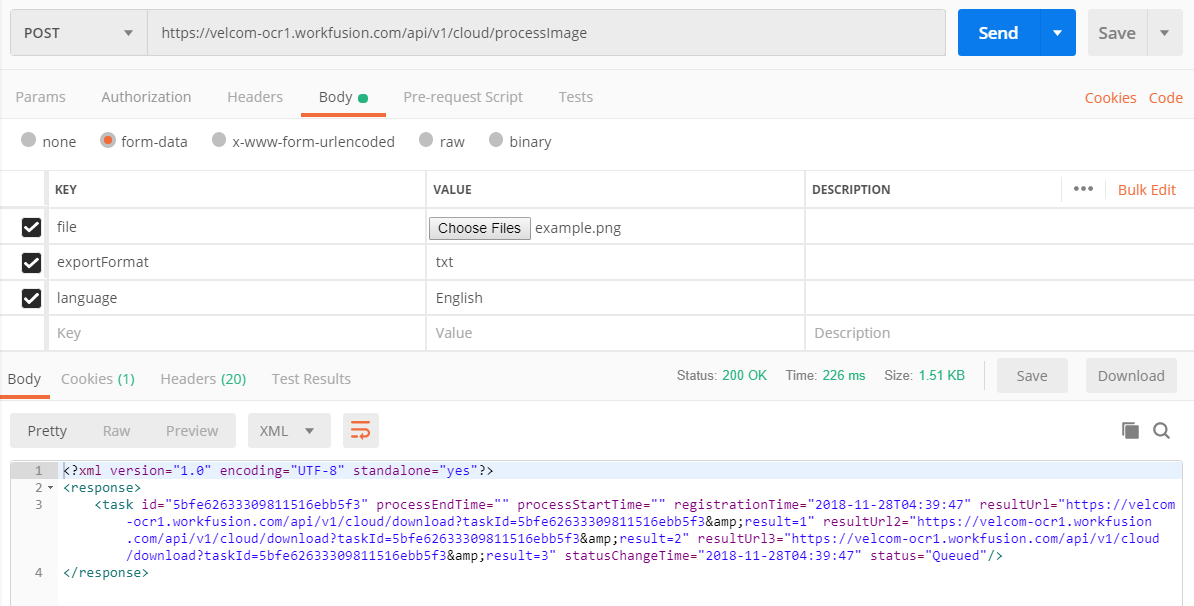
A response has a lot of useful information: taskId, processing time, result Urls, status of recognition.
taskId: used during the next requests in the following steps (copytaskIdfrom a response).ResultUrl: a recognition result is available by this link after completion of recognition.
GET host:port/api/v1/cloud/getTaskStatus?taskId=value
Check task status with getTaskStatus (specify correct taskId).
The taskId value is determined in the previous step.
Set the taskId parameter and send a request.
As a result, the task status with resultUrls are provided in a response.
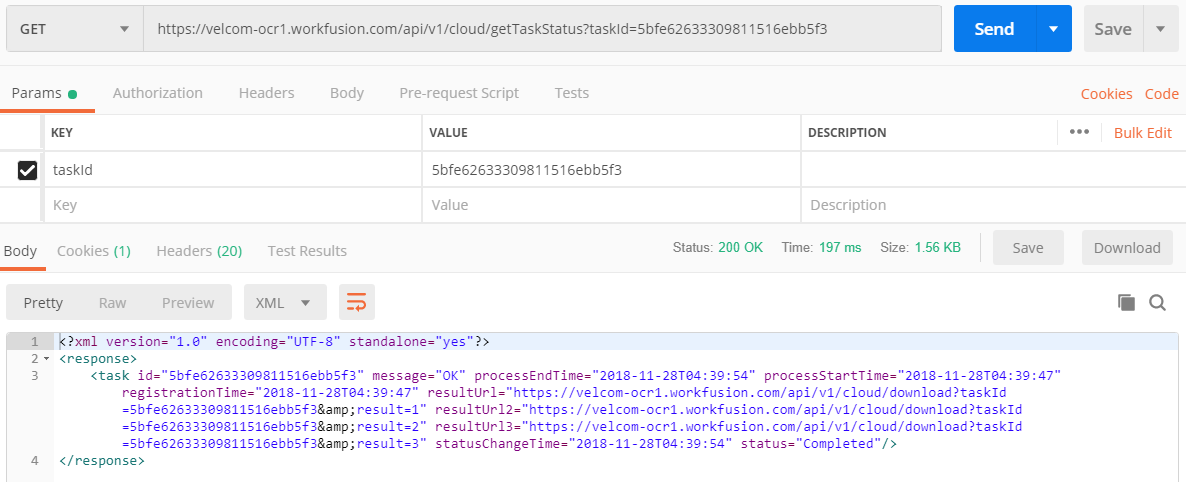
If the task is complete (status="Completed"), open results from the resultUrl, resultUrl2, or resultUrl3 fields (replace & with &).
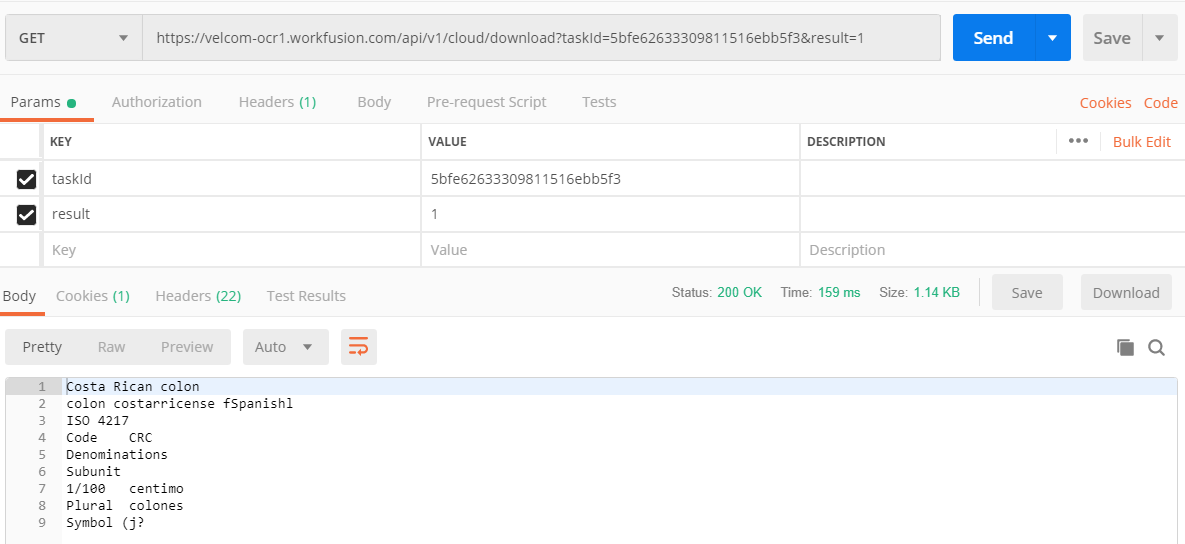
GET host:port/api/v1/cloud/download?taskId=value
If a task is complete (status="Completed"), you can download results from links in resultUrl, resultUrl2, resultUrl3 (depends on the export format).
Recognition via processDocument API
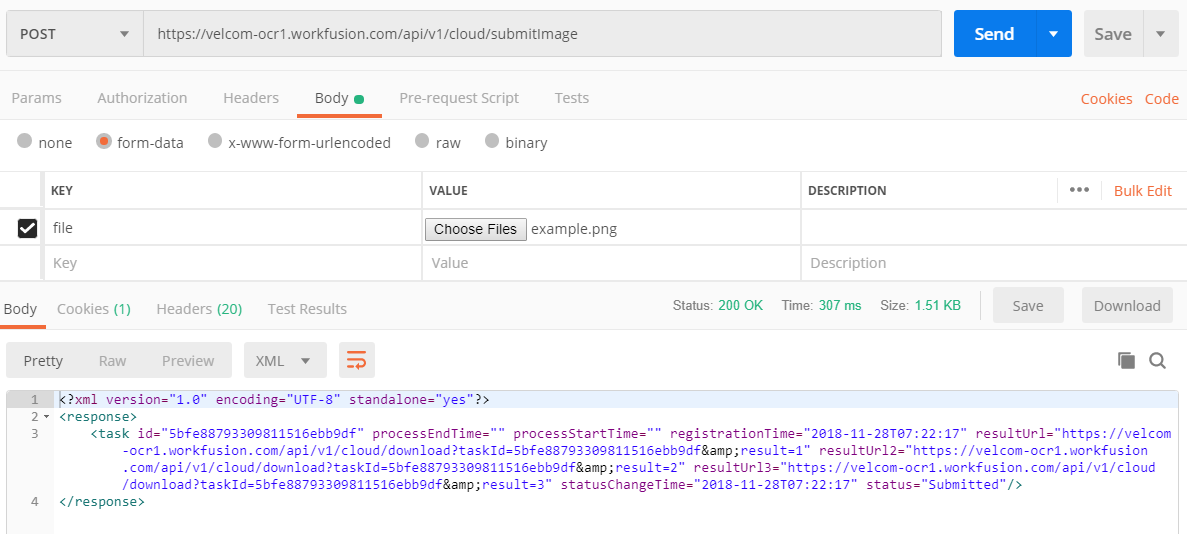
POST host:port/api/v1/cloud/submitImage
Upload a file with submitImage, copy taskId from a response.
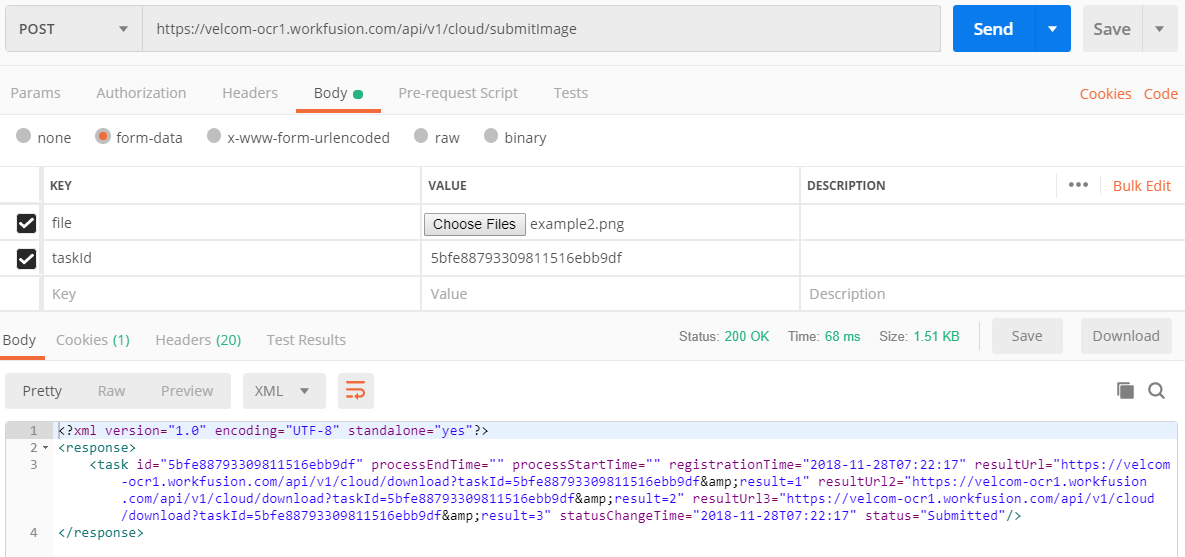
If you need to upload several files for recognition, do as follows:
- Submit an image.
- Copy ID.
- Add the
taskIdparameter to submitImage API. - Submit one more image.
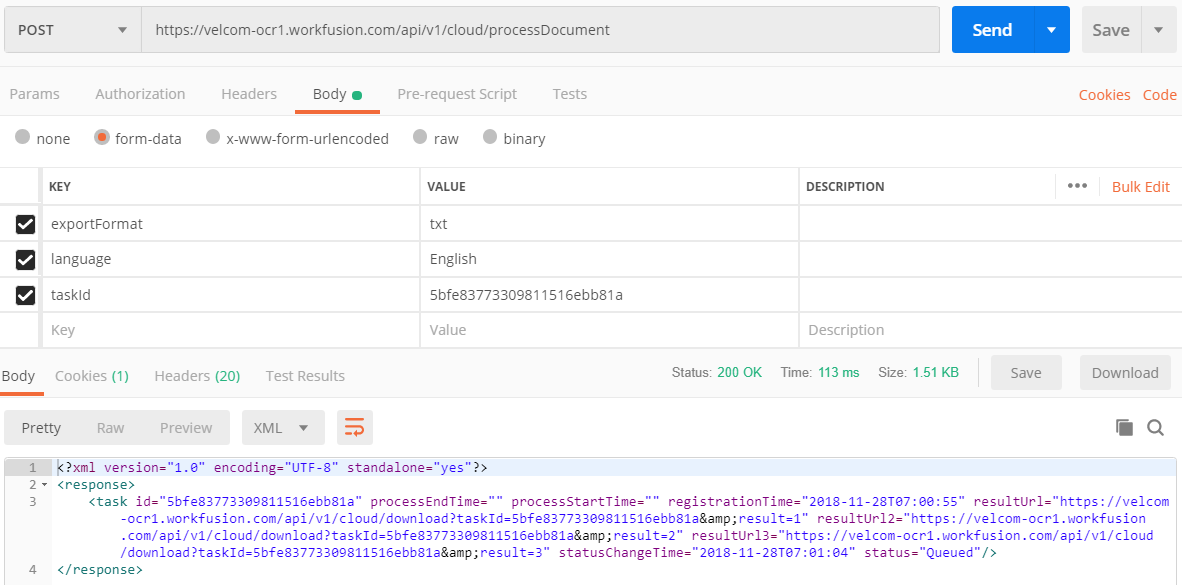
POST host:port/api/v1/cloud/processDocument
Start image processing with processDocument.
- The
taskIdvalue is determined in the previous step. Set thetaskIdparameter. - Add parameters for correct recognition.
- Send a request.
GET host:port/api/v1/cloud/getTaskStatus?taskId=value
Check a task status with getTaskStatus (specify correct taskId).
If a task is complete (status="Completed"), open results from the resultUrl, resultUrl2, or resultUrl3 fields (replace & with &).
GET host:port/api/v1/cloud/download?taskId=value
If a task is complete (status="Completed"), you can also download results from links in resultUrl, resultUrl2, resultUrl3 (depends on the export format).
OCR pattern creation
Extended recognition with a custom trained pattern can be used for:
- Texts set in decorative fonts
- Texts containing unusual characters, for example, mathematical symbols
- Long documents of low print quality (more than a hundred pages)
For example:

The OCR product provides a possibility to create and train a user pattern that will be used for the further recognition.
The pattern training works as follows. Symbols are recognized in the training mode, and, subsequently, a pattern is created. The pattern is used as a source of additional information during recognition to aid recognition of the remaining text.
At first, prepare images and data for training. Then, prepare several examples of symbols in different views and define symbol parameters: baseLine, smallSymbolHeight.
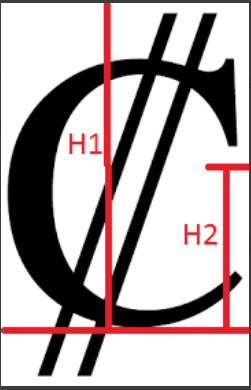
baseLine contains the distance from the base line to the top edge of the cropped image of the character. The base line is the line on which the characters are located.
The top edge of the image is determined by the character orientation: H1 on the picture.
smallSymbolHeightspecifies the height of small characters in pixels on the source image. H2 on the picture.
See the examples below:
| Image | Value |
|---|---|
 |
|
 |
|
 |
|
 |
|
 |
|
 |
|
 |
|
 |
|
 |
|
 |
|
You need to experiment with the baseLine and smallSymbolHeight parameters to optimize recognition.
To determine baseLine and smallSymbolHeight parameters, consider the symbol position on the text line within the actual document. For example, if you consider a checkbox in a tax form, it is much bigger than normal letters, and the base line is slightly higher (1 pixel for W-8BEN-E) than the bottom line of the checkbox. So don't guess the parameters looking at the symbol in isolation, consider the document layout.
Greater pictures of symbols are more efficient for training, preferably around 40-50 pixels.
Generally, you need multiple input images for training.
POST host:port/api/v1/cloud/trainPattern
Set all available examples of a symbol with parameters and required parameters to an API request.
file: image file with the symbol.baseLine: value from the previous step.smallSymbolHeight: value from the previous step.symbol: symbol associated with pictures.
(symbol=₡)
Send and download the trainPattern result as a PTN file.
mergePattern
mergePattern: file upload for a pattern; if provided, the training output pattern is combined with the uploaded pattern.
Prepare images and data for training as was described in OCR pattern creation.
POST host:port/api/v1/cloud/trainPattern
Set all available examples of symbol with parameters and required parameters to an API request.
file: image file with the symbolbaseLine: value from the previous stepsmallSymbolHeight: value from the previous stepsymbol: symbol that is associated with pictures
(symbol=₡)
Use the mergePattern parameter to combine the existing pattern with trained in advanced.
In the current case, ae.ptn is a trained pattern for recognition of the Æ symbol.
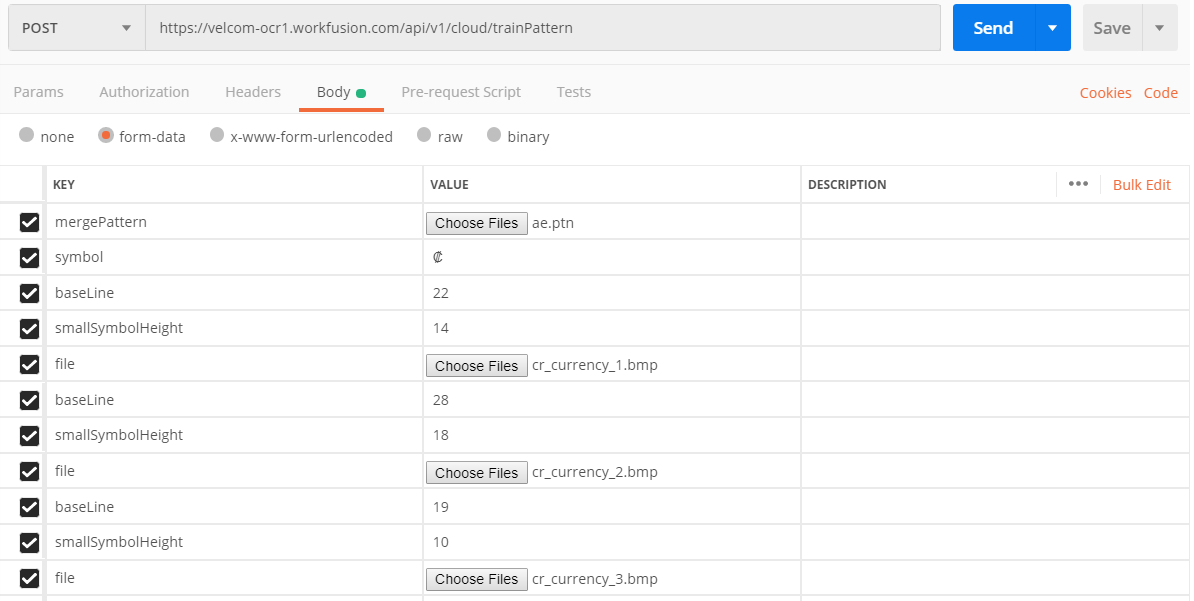
Send and download the trainPattern result as a PTN file.
As a result, the trained pattern is available for recognition of two symbols.
Apply the pattern for the first symbol as described below.
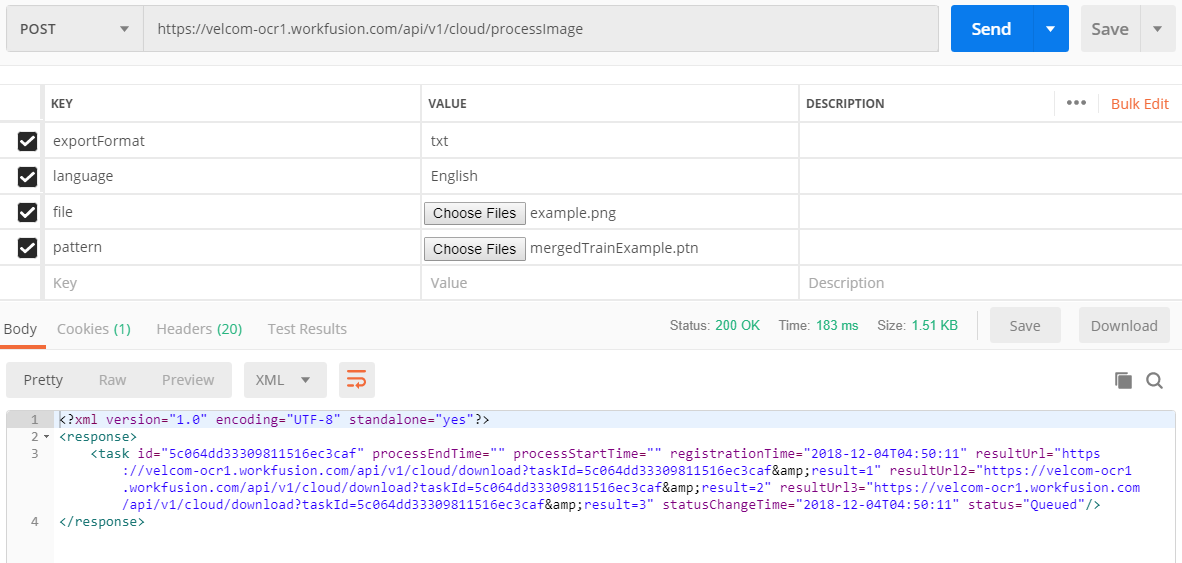
pattern: file upload for a pattern to be applied to recognize special symbols.
- You need the symbol to be added to
alphabetExtension(alphabetExtension = Æ). - You can use either an explicit pattern uploaded with the field or
useDefaultPattern=true, not both.
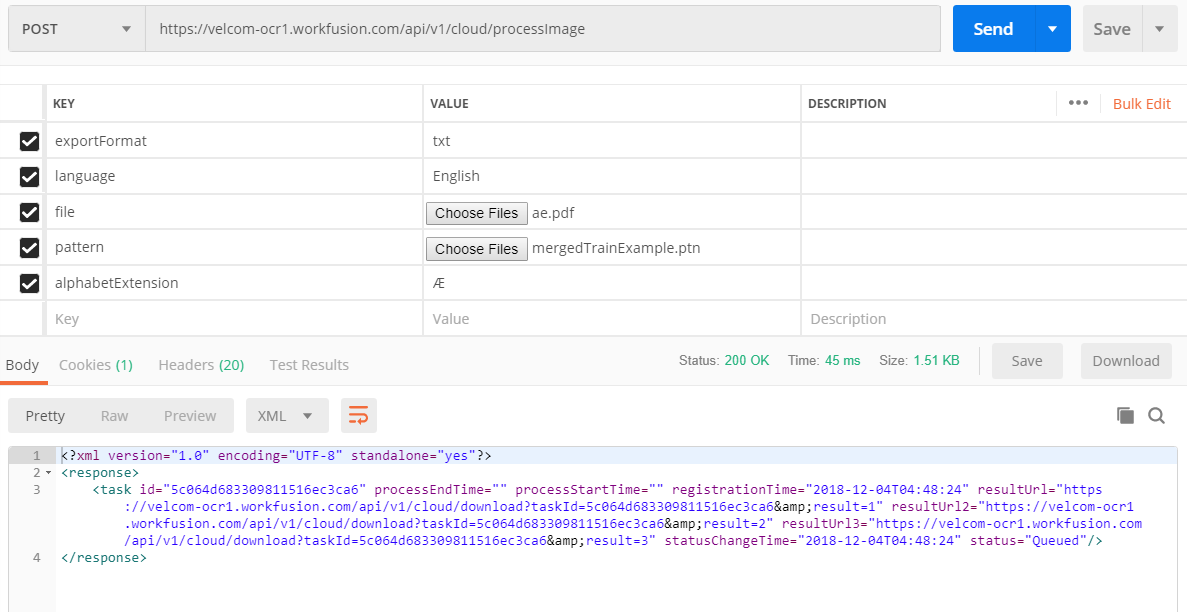
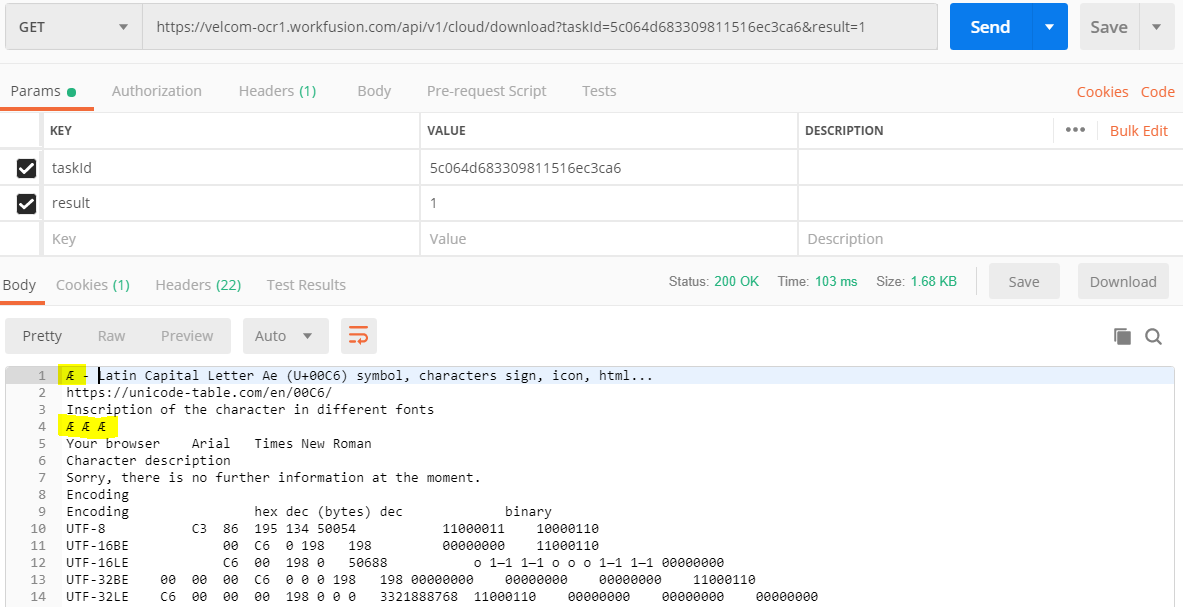
processImage: apply OCR pattern
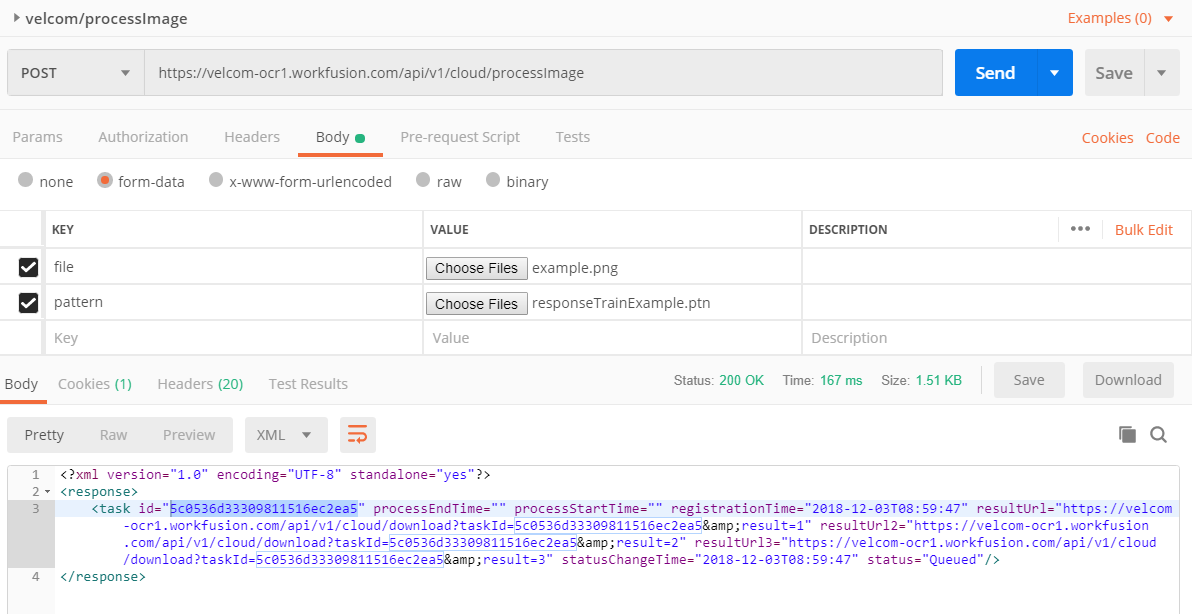
POST host:port/api/v1/cloud/processImage
Add the trainPattern file to the ProcessImage request.
pattern: a file parameter for better recognition.
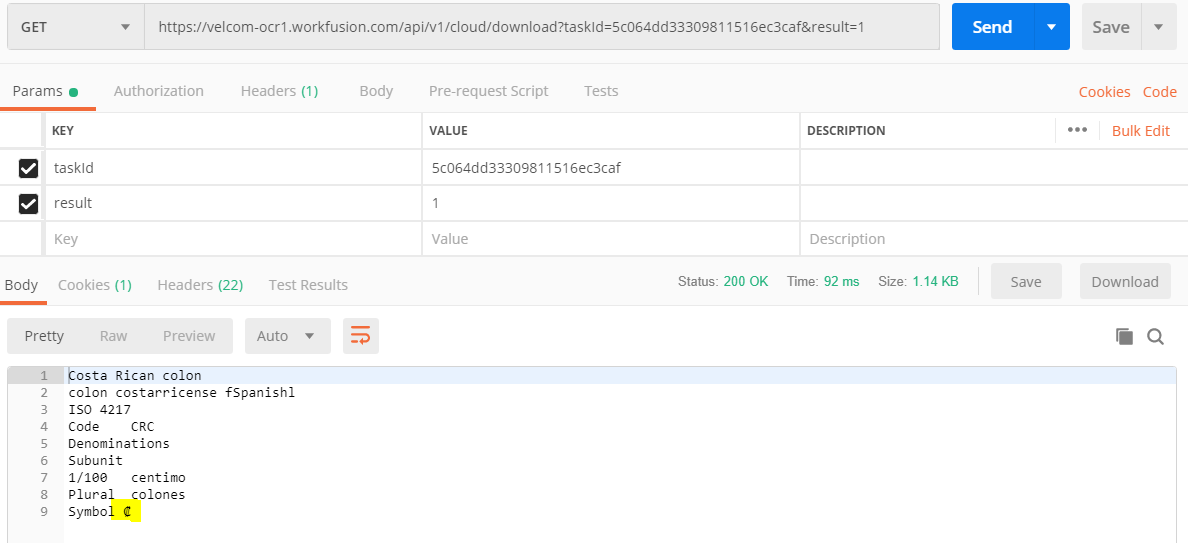
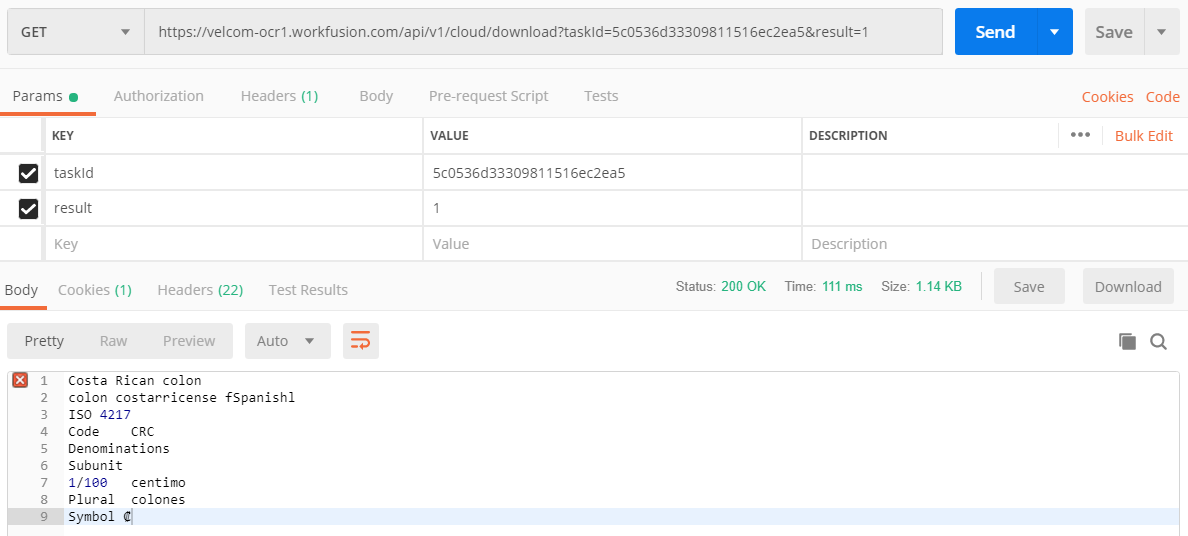
Download results where trainPattern is applied > symbol ₡ iss recognized as expected.
processDocument: apply OCR pattern
First, submit an image for recognition.
POST host:port/api/v1/cloud/submitImage
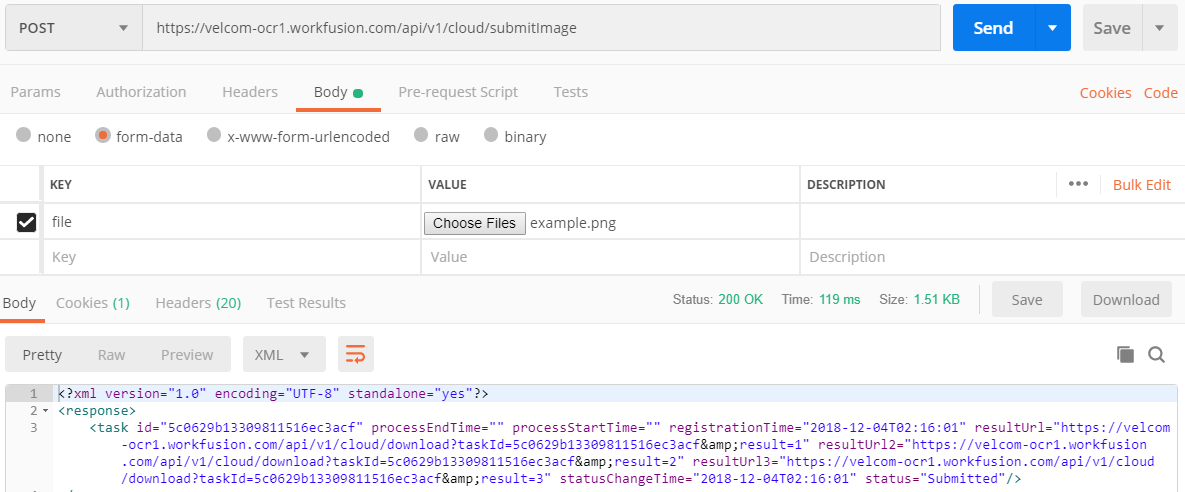
Copy ID for the subsequent steps.
After that, apply submitPattern trained and downloaded before.
POST host:port/api/v1/cloud/submitPattern
The taskId value is determined in the previous step.
Set the taskId parameter and a pattern file.
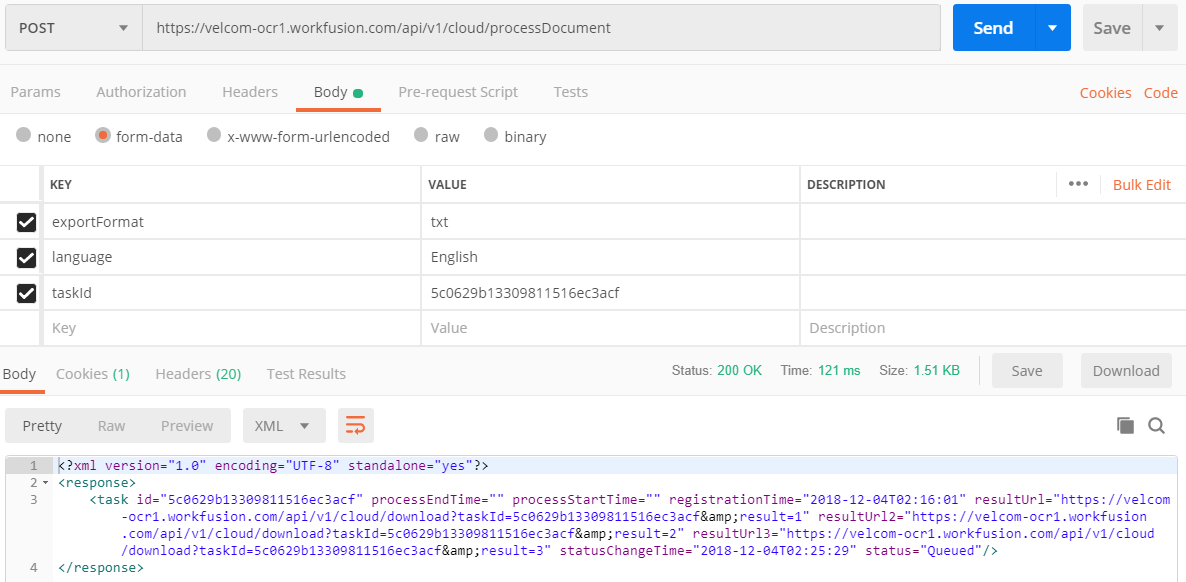
POST host:port/api/v1/cloud/processDocument
Start image processing with processDocument. The trained pattern was uploaded in the previous step.
Set the
taskIdparameter.Add parameters for correct recognition.
Send a request.
Download results where
trainPatternis applied > symbol ₡ was recognized as expected.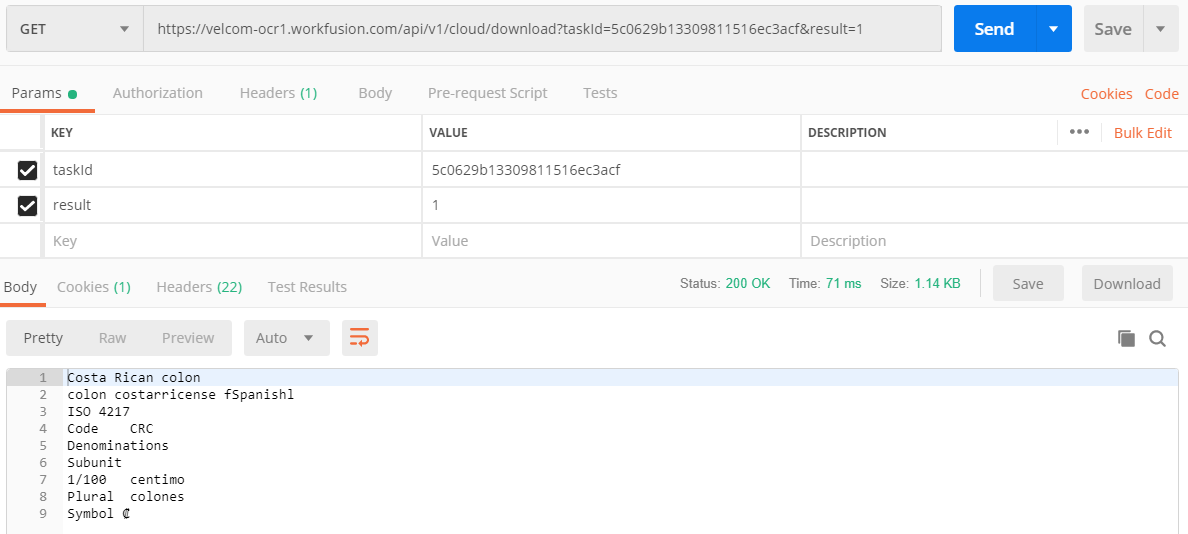
Practical usage tips
Recognition quality
- Use custom
dictionary. - Fetch plain text from pdf and set it to the
originalTextparameter. - Don't use the
removeGarbageSizeparameter for PDF searchable and carefully use it for scanned PDF or image. Sometimes, it can degrade results. - Train and use pattern for some repeatable unrecognized cases. By default, the
costa_rica_currencypattern. - PDF searchable document is preferable to recognition than high DPI image created from it.
- Recommended resolution for source image: 300 DPI for typical texts (10 pt or larger) and 400-600 DPI for texts in smaller fonts (9 pt or smaller).
Performance improvements
- Use
skipPreprocessing=trueat least for PDF searchable documents. It saves up to 30% processing time - Use
xml:writeRecognitionVariants=falseif you don't need char or word variants in the output XML file. It saves up to 30% processing time, memory and disk space.