Manage models
To access a list of available machine learning (ML) models, select AutoML > Models. Control Tower updates the list every time a new model is deployed to your environment or you complete a training run.
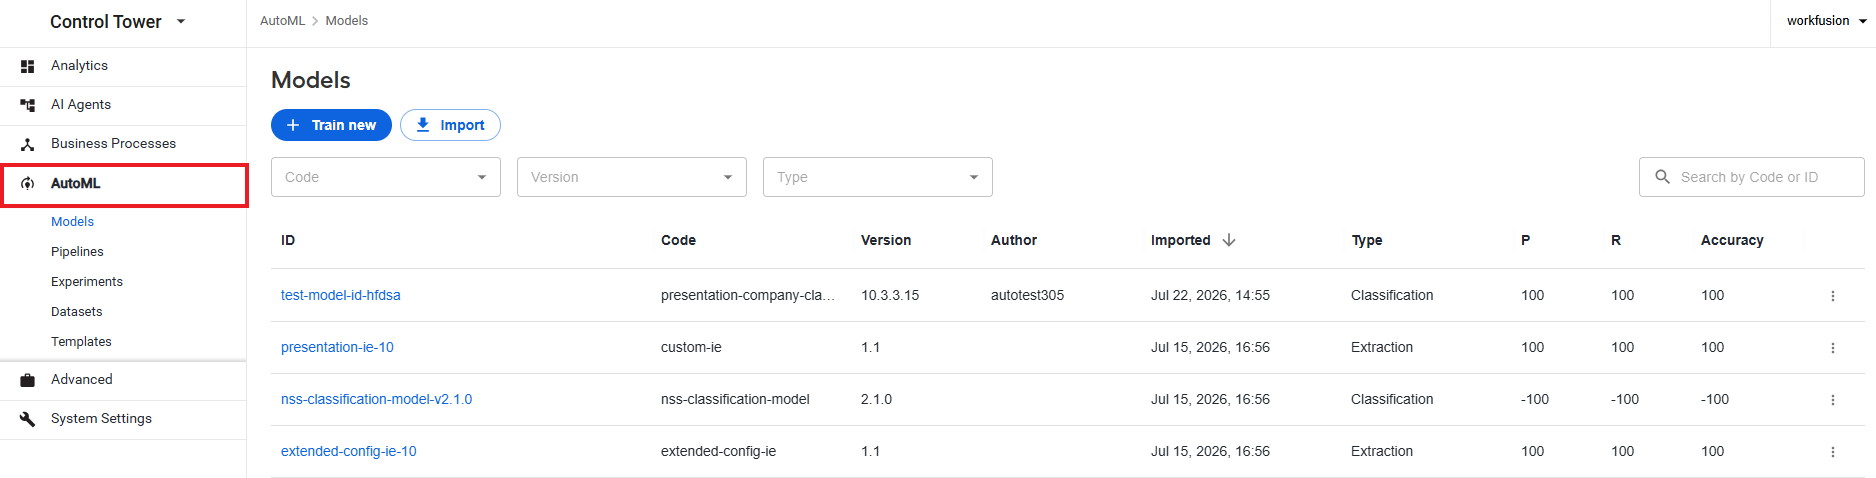
From the list, you can find out the following information about each available ML model:
| Column | Description |
|---|---|
| ID | Model identifier specified during model training. |
| Code | Pipeline identifier specified in the model's source code description. |
| Version | Pipeline version specified in the model's source code description. |
| Author | Name of the user who created or imported the model. |
| Imported | Date and time (in the dd.mm.yyyy, hh:mm format) when the model was added to your environment. New models appear in an environment either via explicit import operations or after training. |
| Type | Model type identifying its working principle (for instance, extraction or classification). |
| P | Precision of the model calculated based on training results. |
| R | Recall of the model calculated based on training results. |
| Accuracy | Accuracy rate for the model calculated based on training results. |
To get information about models available in Work.AI, see Learn about WorkFusion models.
View model details
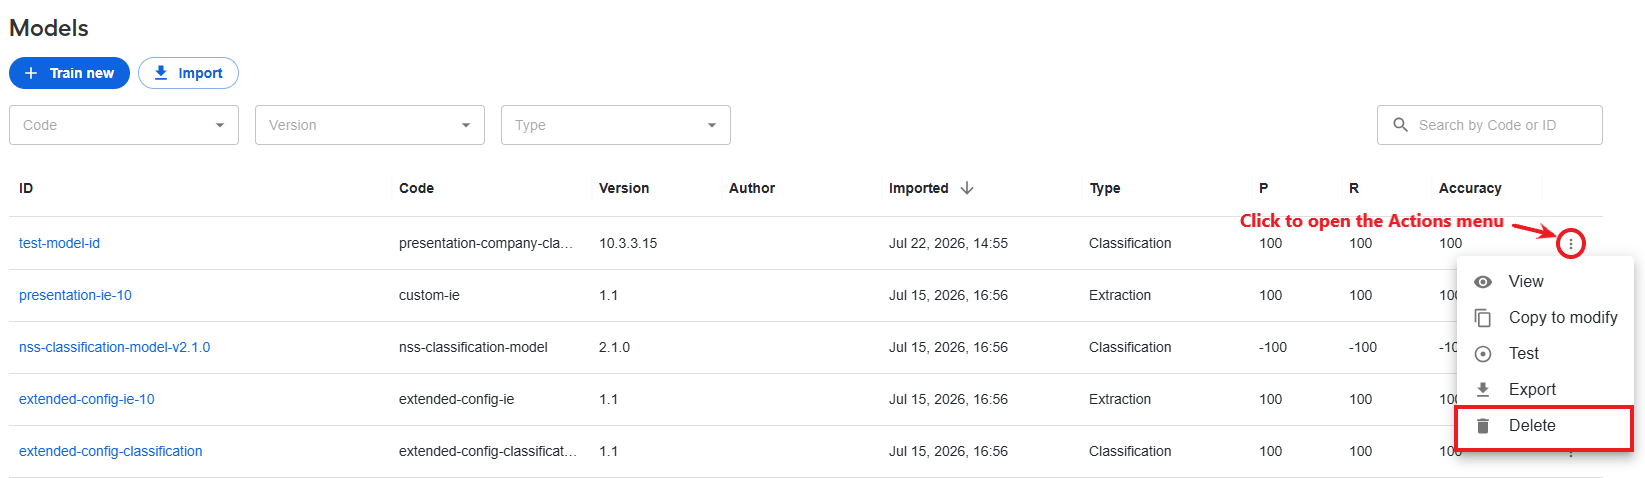
To view the detailed data for a particular model, click its ID in the list or open its Actions menu and select View.
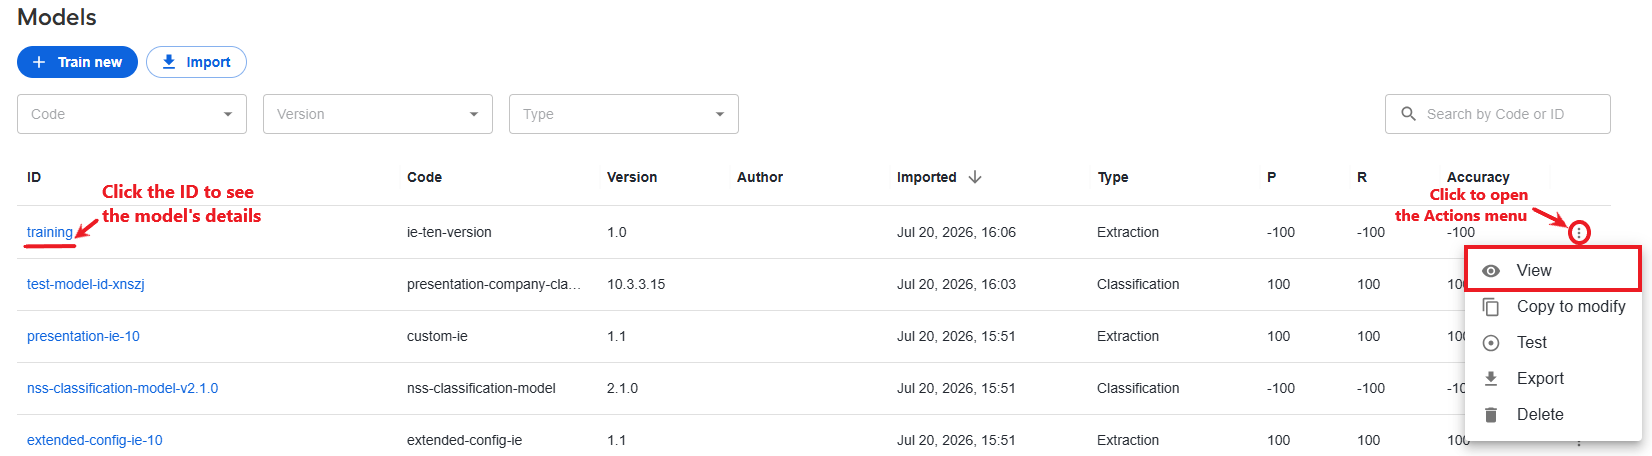
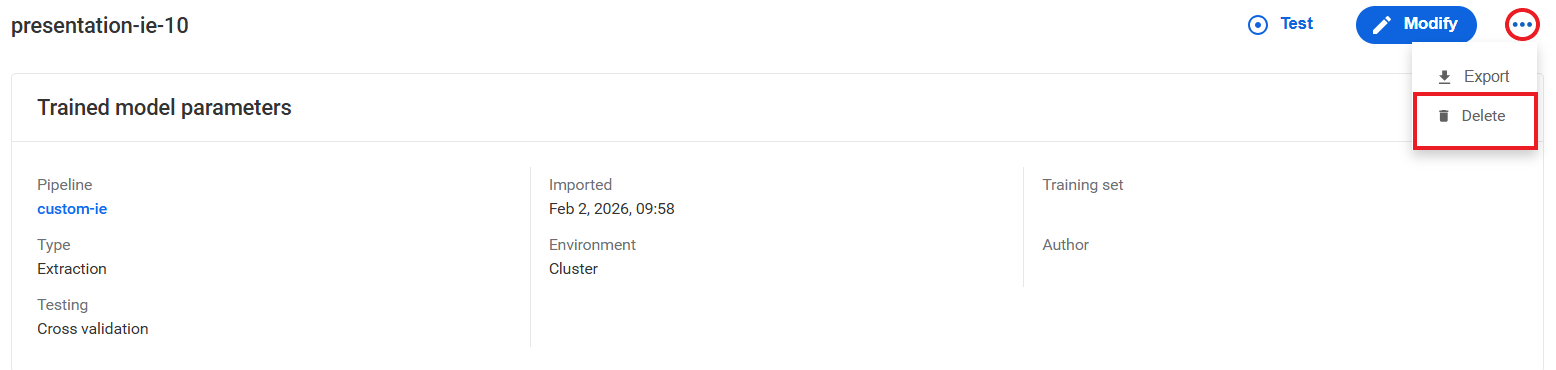
The model details page is displayed:
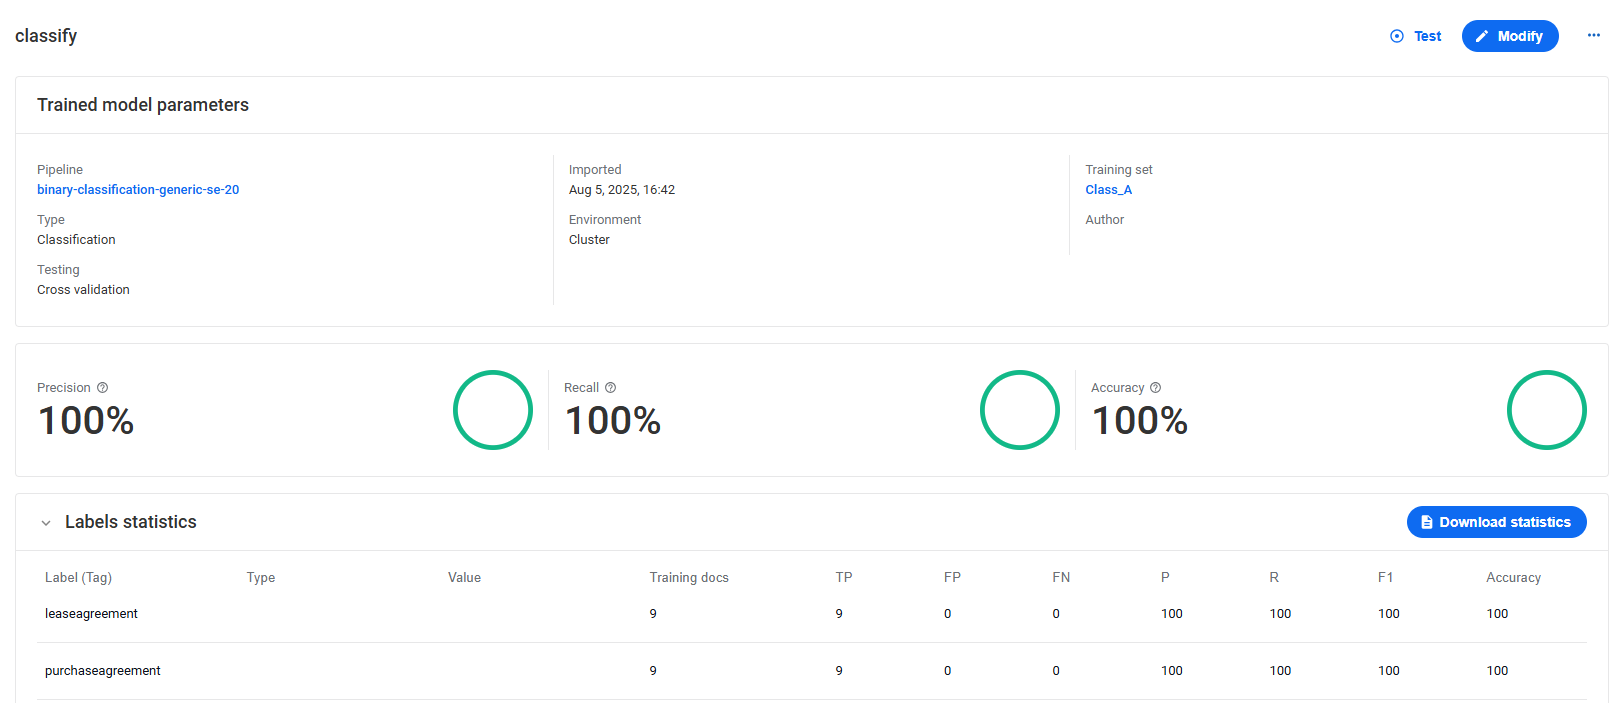
The exact appearance of the page depends on which data is available for a specific model. In particular, it can comprise all or any of the following data items:
| Data item | Description |
|---|---|
| Pipeline | Model's pipeline identifier (Code in the Models list); clicking the link brings you to the page with the pipeline details. |
| Type | Model type identifying its working principle, for instance, extraction. |
| Testing or Test set | Model's test method:
|
| Imported | Timestamp (dd.mm.yyyy, hh:mm) when the model was imported to Control Tower. |
| Environment | Model's environment data. |
| Training set | Name of the dataset used for model training; clicking the link brings you to the page with the dataset details. |
| Overall model statistics | Precision, recall, and accuracy diagrams depicting average metrics for the total of data points (labels) in percent. |
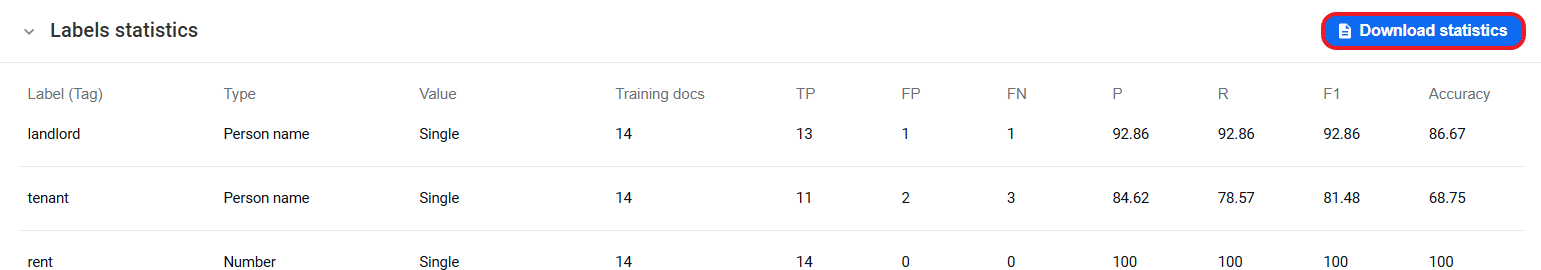
| Label statistics | Various metrics associated with each model data point (label):
|
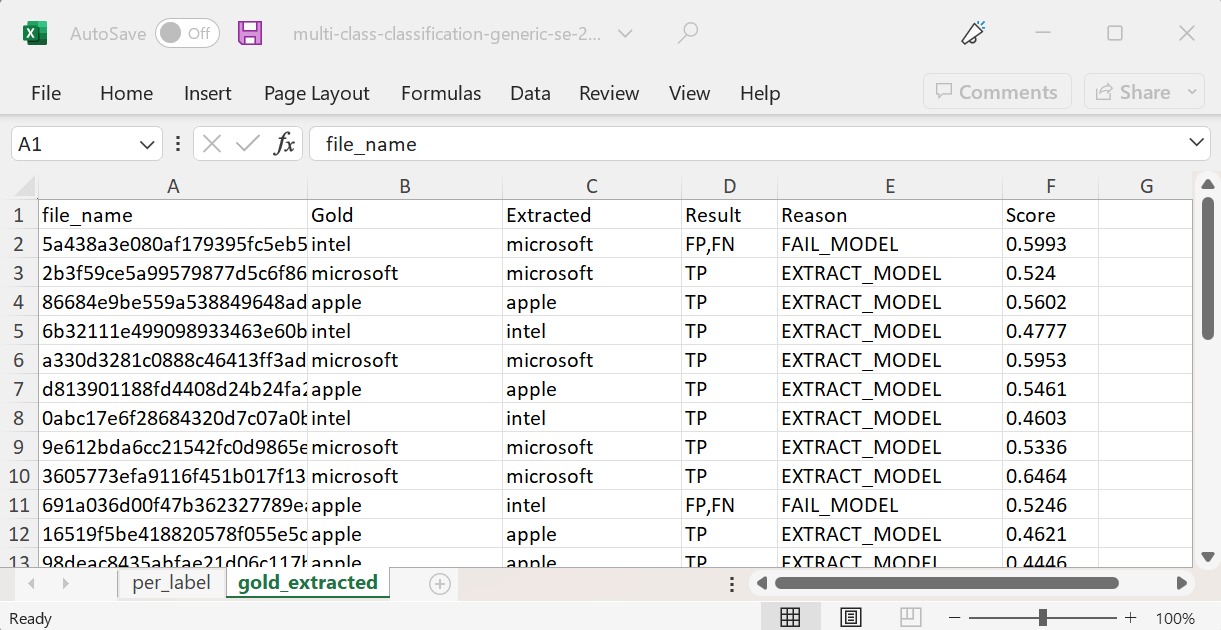
To export the label statistics (if available) as an XLXS file, click Download statistics.
For models developed with AutoML SDK of version 10.2.6 and higher, the XLXS statistics file also includes extended per document statistics.
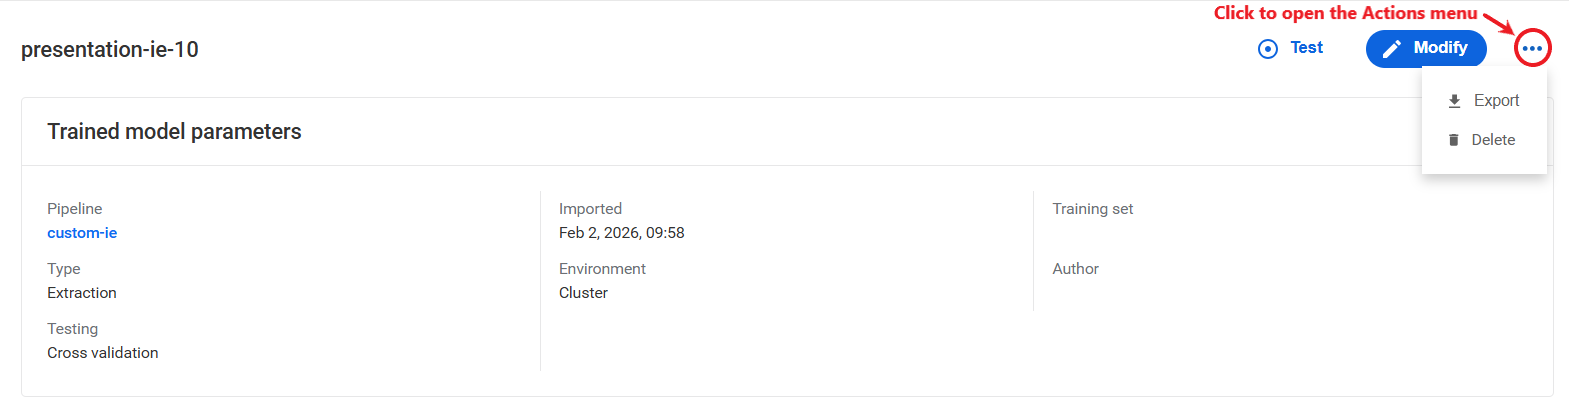
From the model details page, you can also do the following:
Start the flow to modify the model by clicking the Modify button. See Modify model.
Launch a test for the model by clicking the Test button. See Test model.
Export the model as a zip archive. See Export model.
Delete the model. See Delete model.
Convert ML Ops-trained models into BEP-compatible ones. See Convert ML Ops-trained models into BEP-compatible.
Filter and search
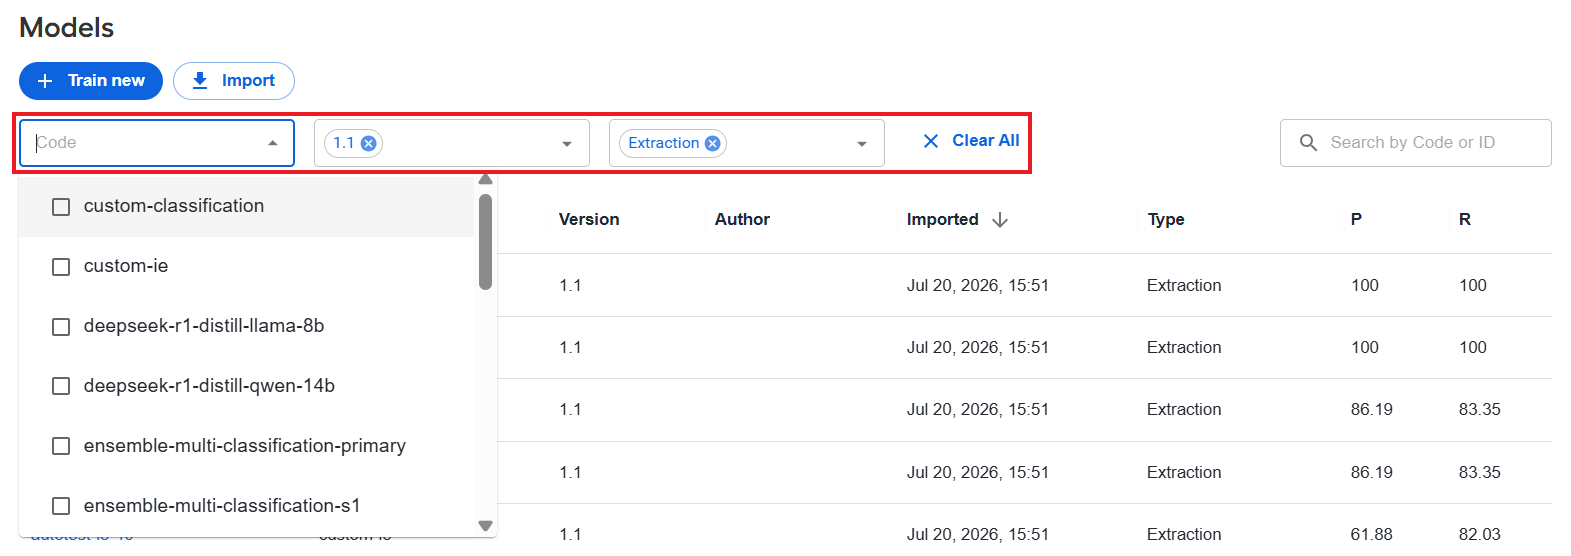
You can filter the list of displayed models based on any or all the three criteria:
- Model's pipeline code
- Pipeline version
- Model type
To apply the criteria, select filters from the drop-down boxes at the top of the Models list. Selected filters appear as visible options inside the drop-down boxes, and the items in the Models list change accordingly to show the filtering results.
To turn off an active filter, click its cross button. To reset all filters, click Clear all.
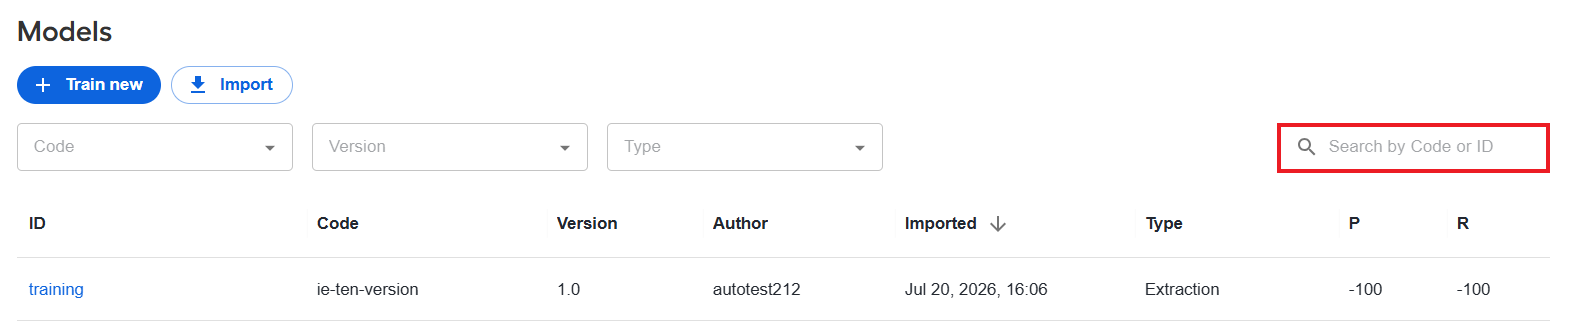
You can also search the list for particular models using the Search by Code or ID box in the top-right corner.
Create model in no-code manner
In the AutoML UI in Control Tower, you can create a model in one of the two ways:
Alternatively, you can launch model training as follows:
From the Pipelines list. For details, read Manage pipelines | Train model.
Via Experiments > Trainings. For details, read Run experiments | Start training.
Train new model
To train a new model based on an available pipeline, follow the steps below:
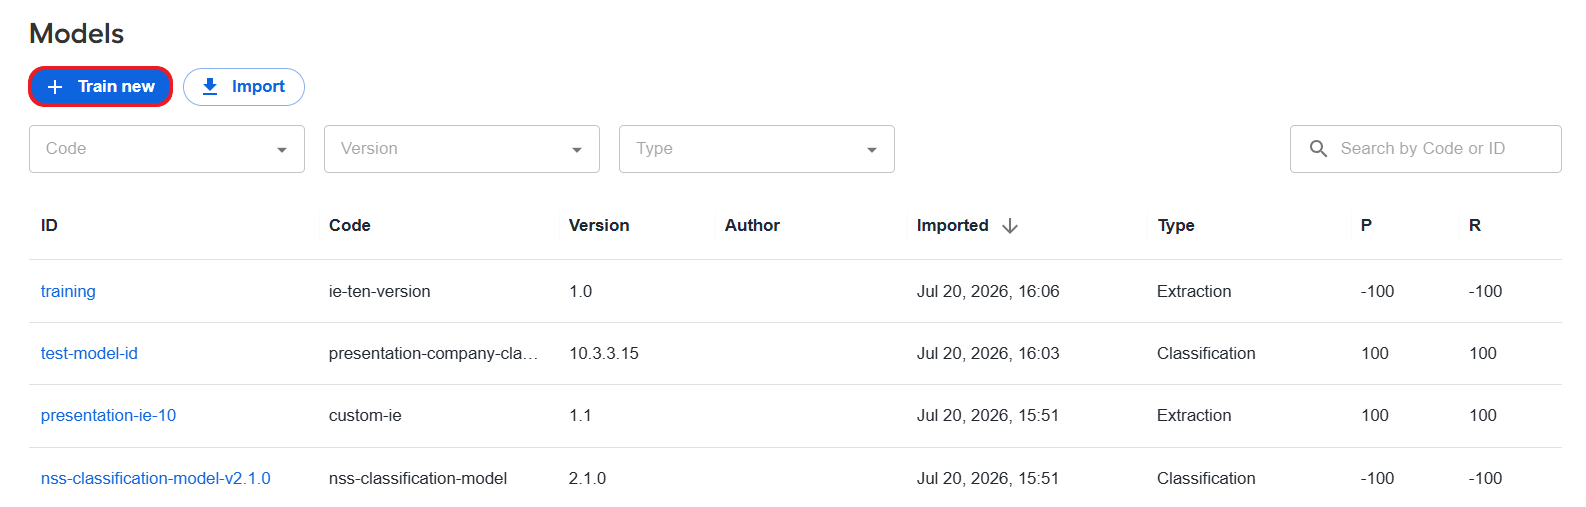
On the Models page, click Train new.
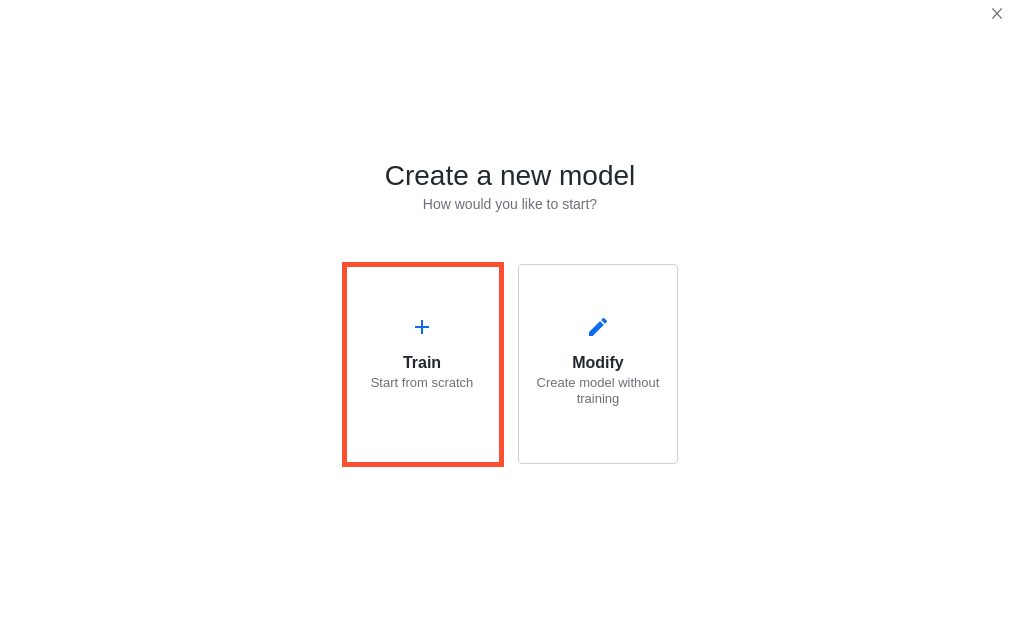
To create a model from scratch, click Train.
To configure a pipeline for the new model, fill in the fields as described below:
Specify a unique model ID so that you and other users can quickly identify the new model among others.
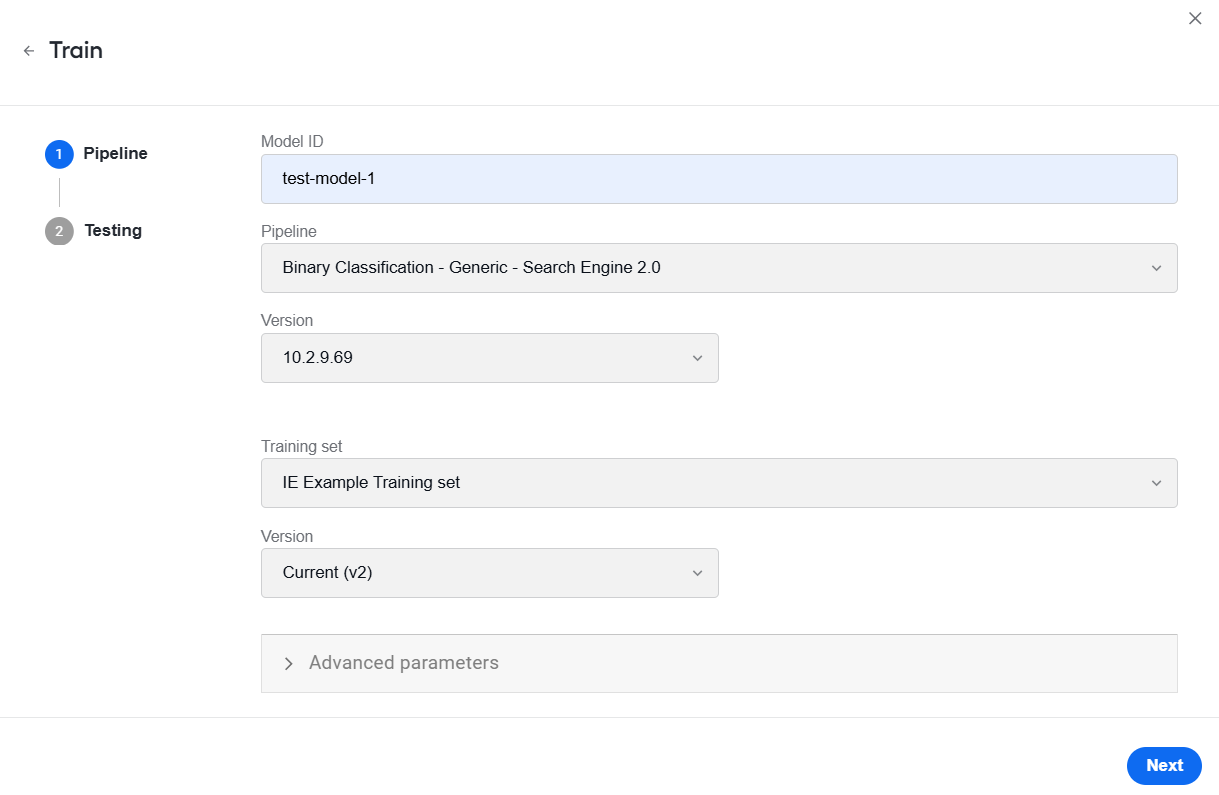
Choose a pipeline and its version from respective drop-down lists.
In the Training set drop-down list, select a dataset for training the model and choose its version.
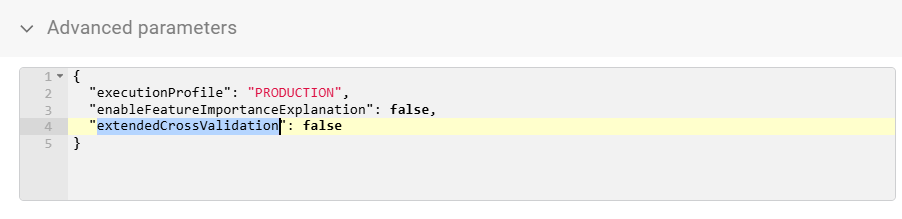
Optionally, set advanced model training and execution parameters. By default, the Advanced parameters JSON editor displays the following parameters:
executionProfiledefines if evaluation results and metadata for them should be preserved (DEBUGmode). Possible values arePRODUCTION(default) andDEBUG.enableFeatureImportanceExplanationprints top N features, each with detailed info and score. Possible values areTRUE(default) andFALSE.extendedCrossValidationis a Boolean flag defining whether to apply extended cross-validation or not. Possible values areTRUE(default) andFALSE.
For a full list of model training and execution parameters, read the Perform advanced model tuning in AutoML UI topic.
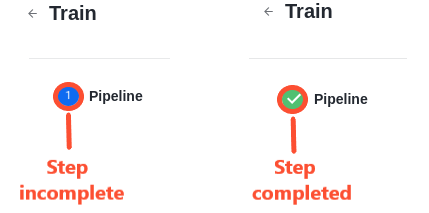
Click Next to continue. Clicking the button causes the flow of training steps on the left to change, depending on the model configuration contained in the pipeline you specified. The completed step is marked with a green tick as shown below:
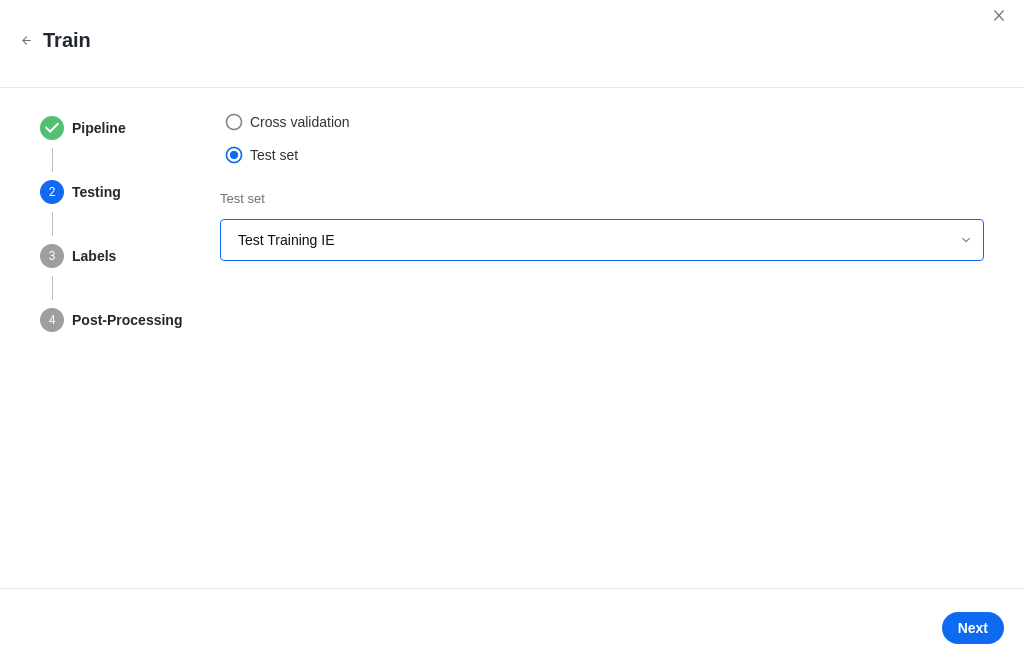
On the Testing step, choose a testing method. If you select Test set, specify one in the appropriate field. As you start typing in the field, available options appear as a drop-down list.
To proceed to the next step, click Next.
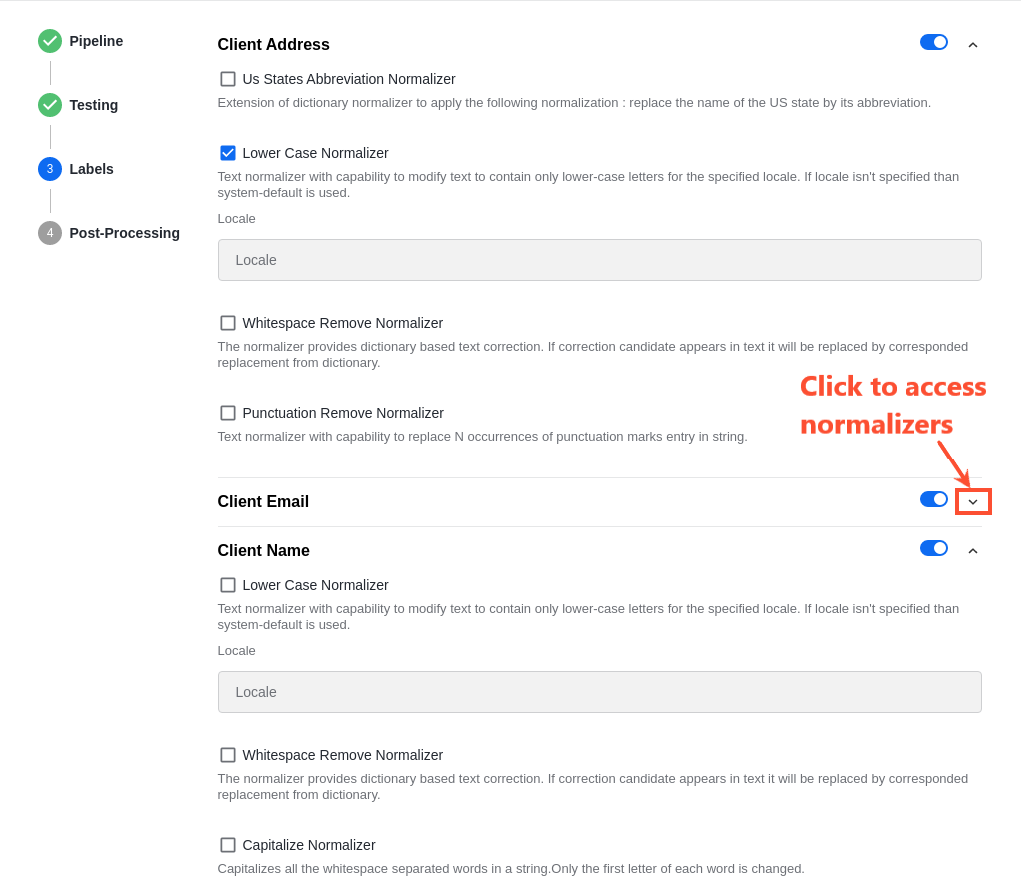
For classification models, the step is not required and not available. For models other than the classification type, configure labels and normalizers and click Next to continue:
To configure labels, toggle buttons on or off. The initial list of labels is fetched from the selected training dataset and the initial configuration—from the model's pipeline.
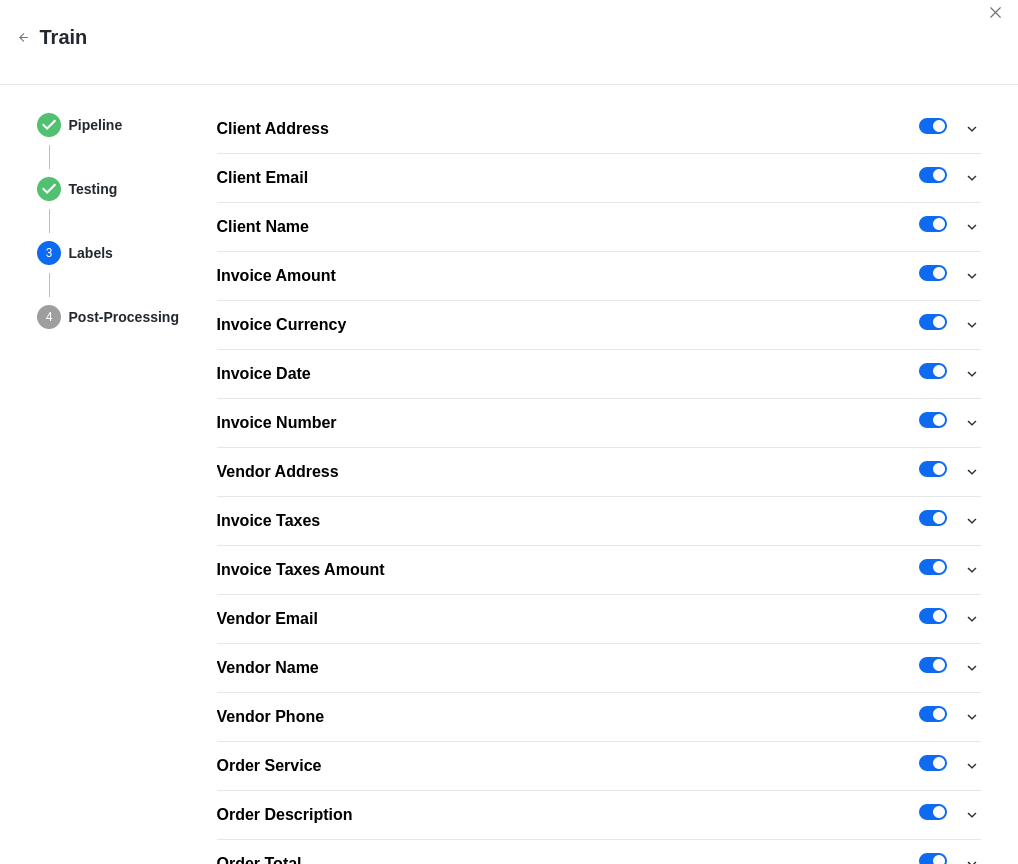
To configure normalizers, click the arrow button next to a specific label and make appropriate changes. The initial normalizer configuration is fetched from the model's pipeline. For a normalizer setup example, refer to the article.
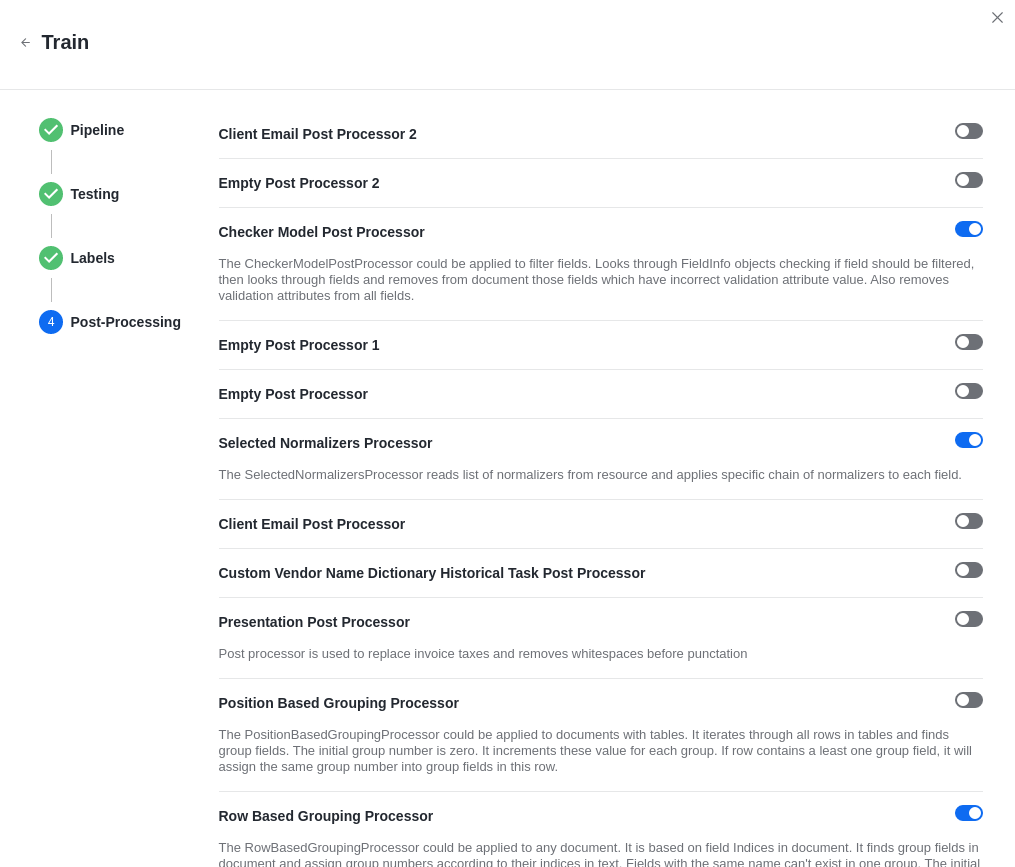
Configure post-processors (if any) by switching toggles on and off and click Next to proceed. The initial post-processor configuration is fetched from the model's pipeline.
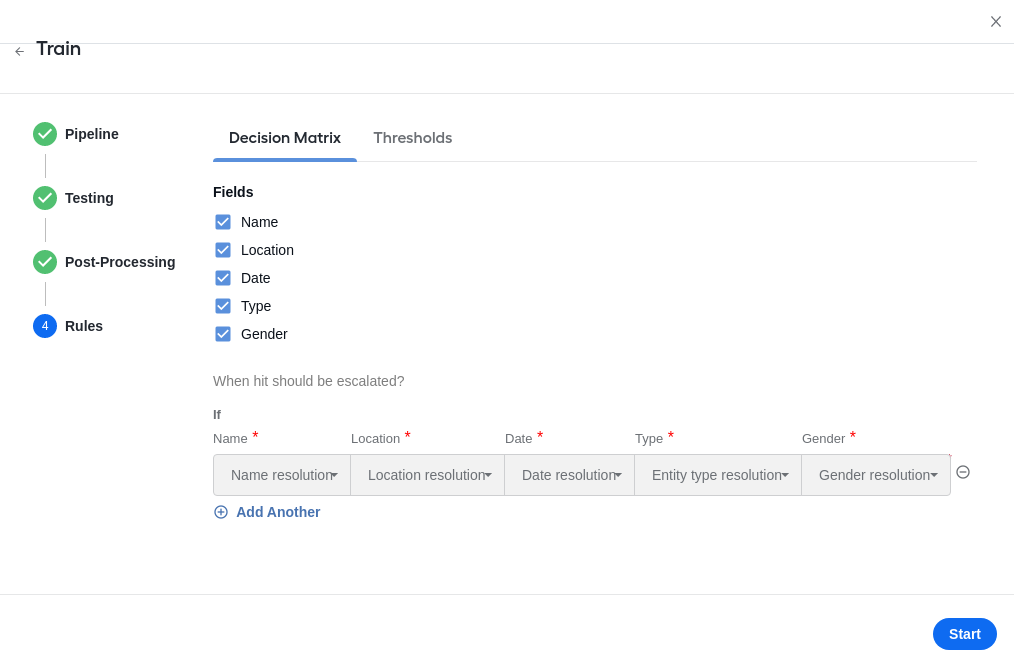
Configure the decision rules (if any) as appropriate for your process. The initial rule configuration is fetched from the model's pipeline.
Once you are done with the configuration, click Start to launch the model training.
To check whether the training started successfully, navigate to AutoML > Experiments. On the Trainings tab, find the new model training run: its status should be In progress.
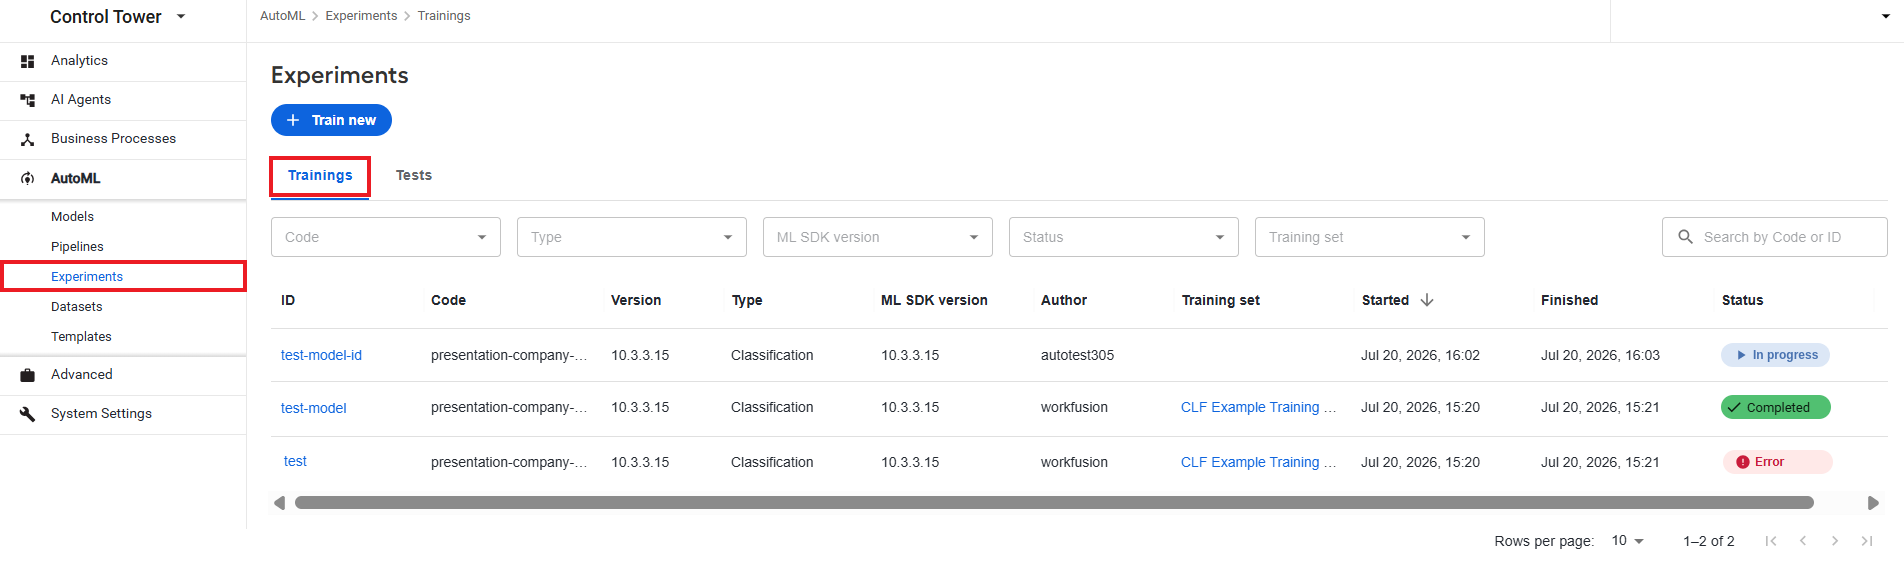
Wait till the status changes to Completed. Now, you can click the training ID and review the resulting model data.
Alternatively, to access the data, act as described in the View model details section above.
Modify model
The modifying flow lets you update configurations of existing ML models without training them. As a result, you get a new artifact with an updated configuration.
Start flow
There are two methods for starting the model modification flow:
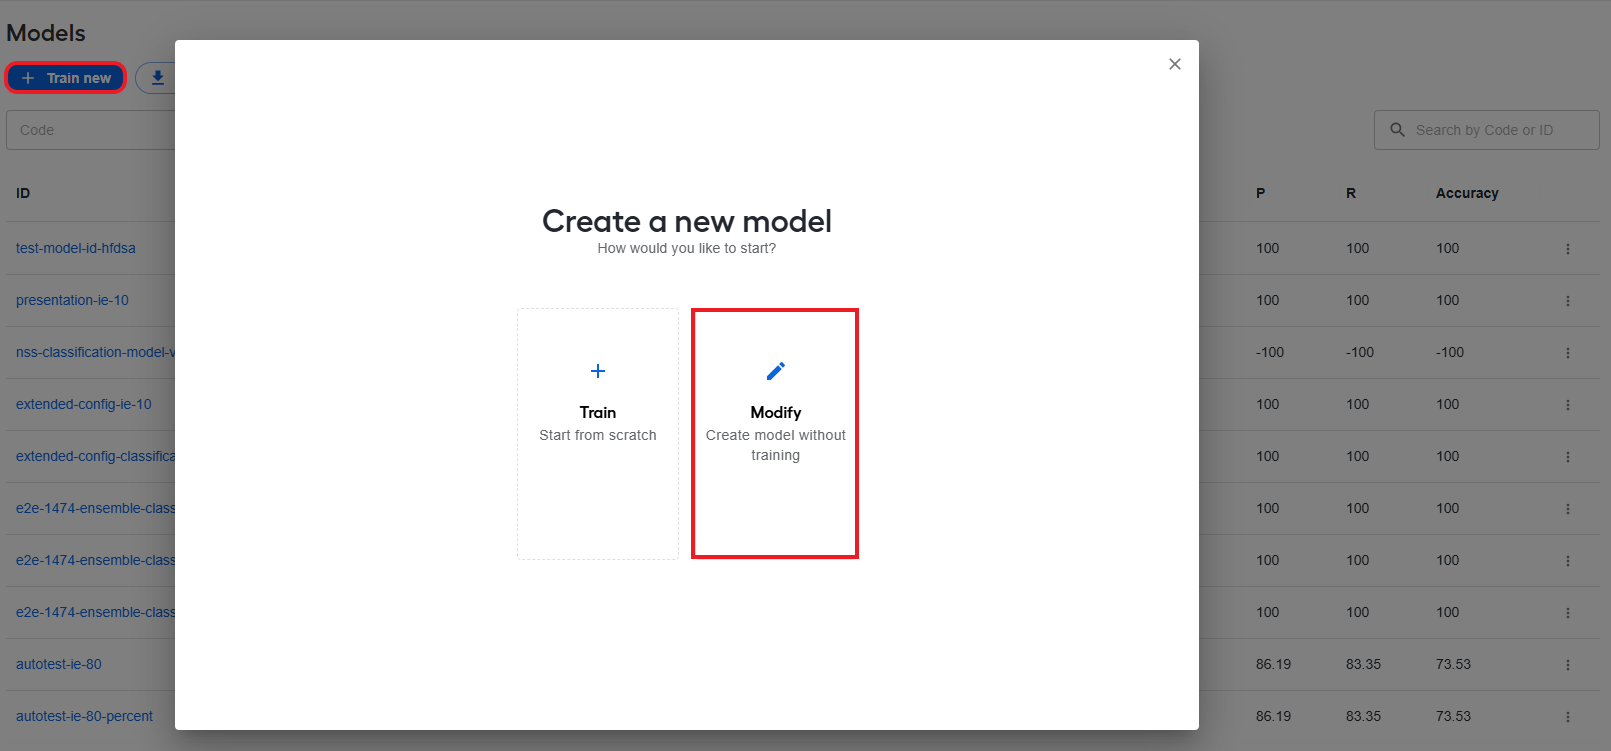
On the Models page, click Train new, select Modify, and follow the instructions in the Update configuration section.
On the Models page, open the Actions menu for a specific model, click Copy to modify, and follow the instructions in the Update configuration section.
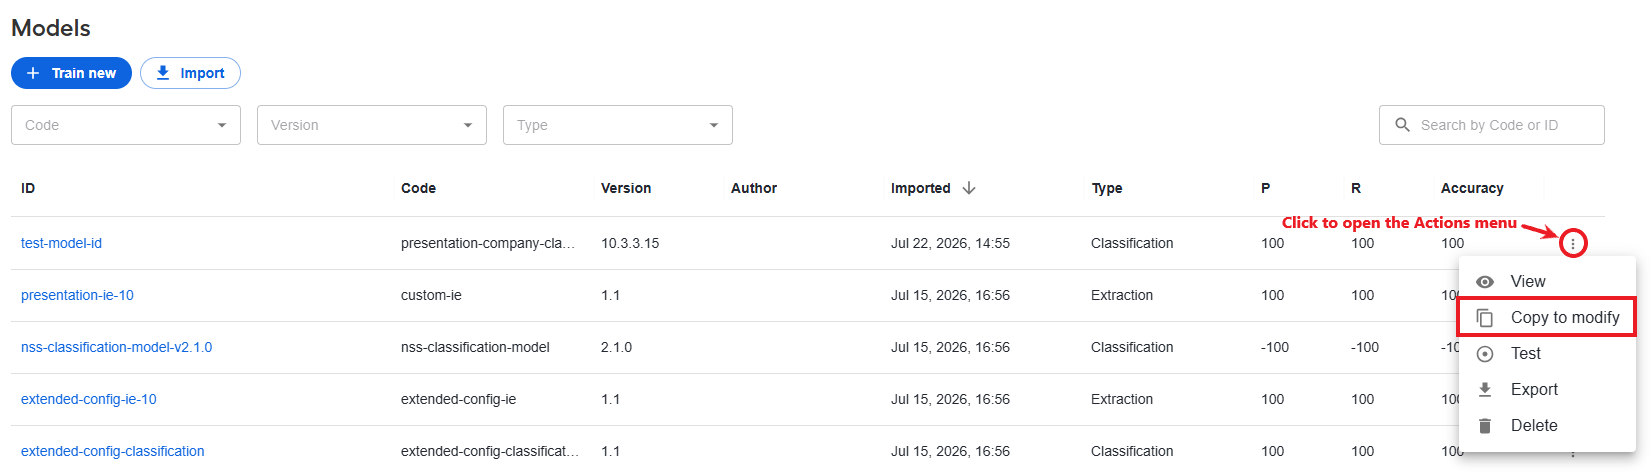
When you start the flow from copying, mind that it comprises two stages:
You select a model to update, and a copy of the model is created.
A test is launched for the copied model.
If the copying stage fails, a model is not created. When the test stage fails, a model artifact is created, but the statics is not available.
Update configuration
In the Modify dialog, follow the steps below to create a model:
Select a prototype to modify and specify a new model ID. If you start from Copy to modify, the prototype is already selected for you: it's the model you copied.
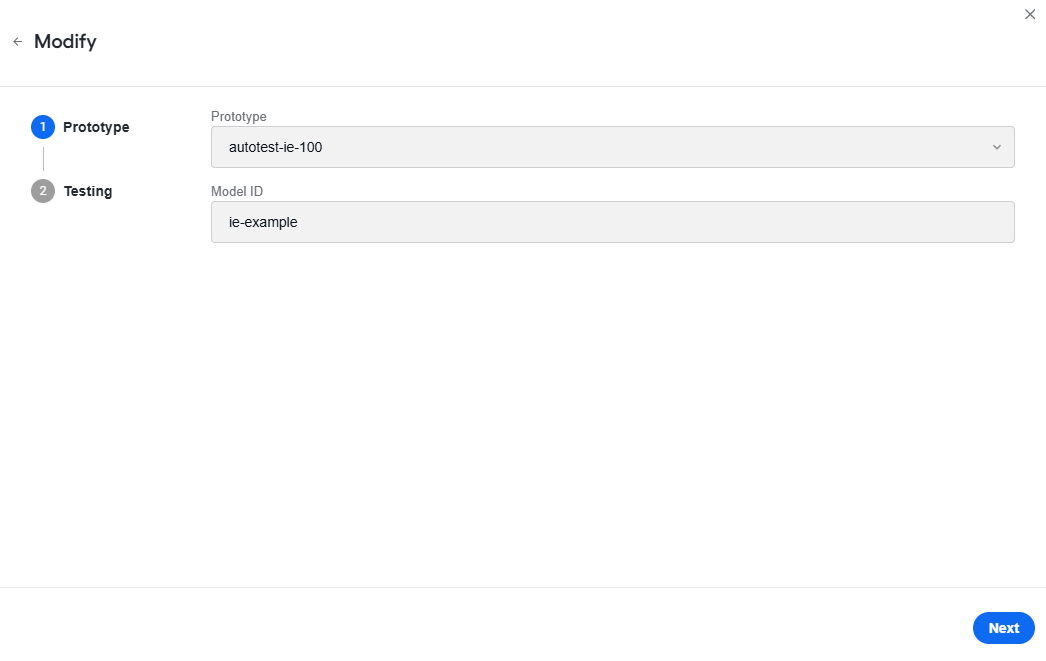
Click Next to proceed. On the right, you can see more steps. Each completed step is marked with a green tick.
On the Testing step, select a test set and click Next.
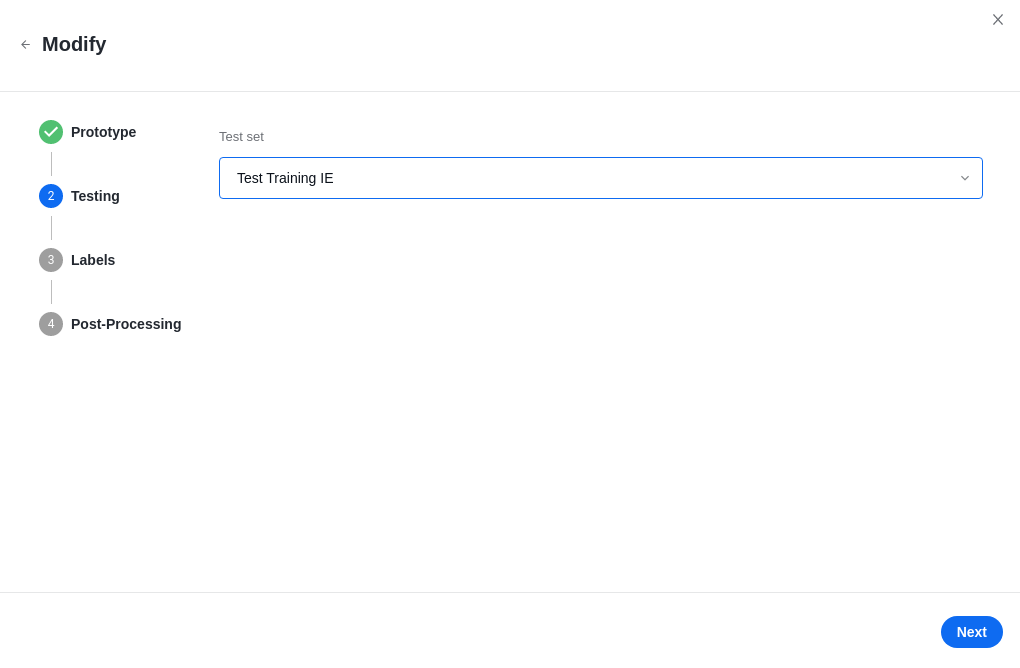
For classification models, the step is not required and not available. For models other than the classification type, configure labels and normalizers and click Next to continue.
To configure labels, toggle buttons on or off. The initial list of labels is fetched from the selected training dataset and the initial configuration—from the model's pipeline.
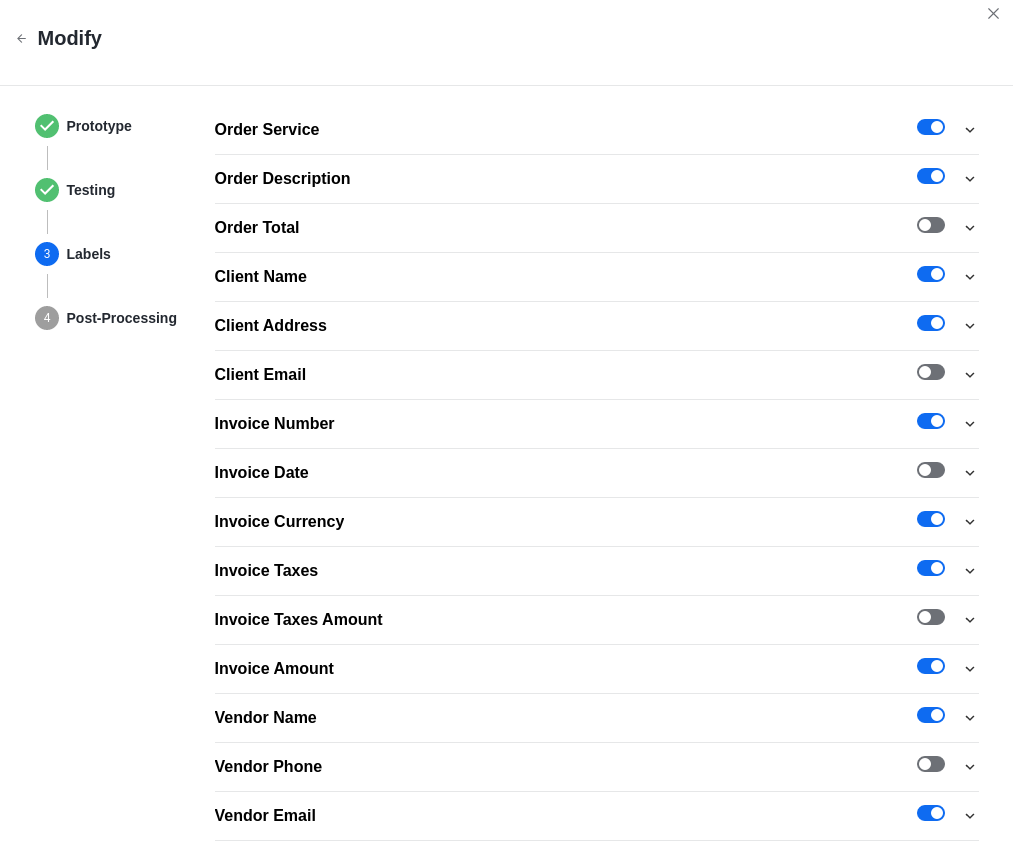
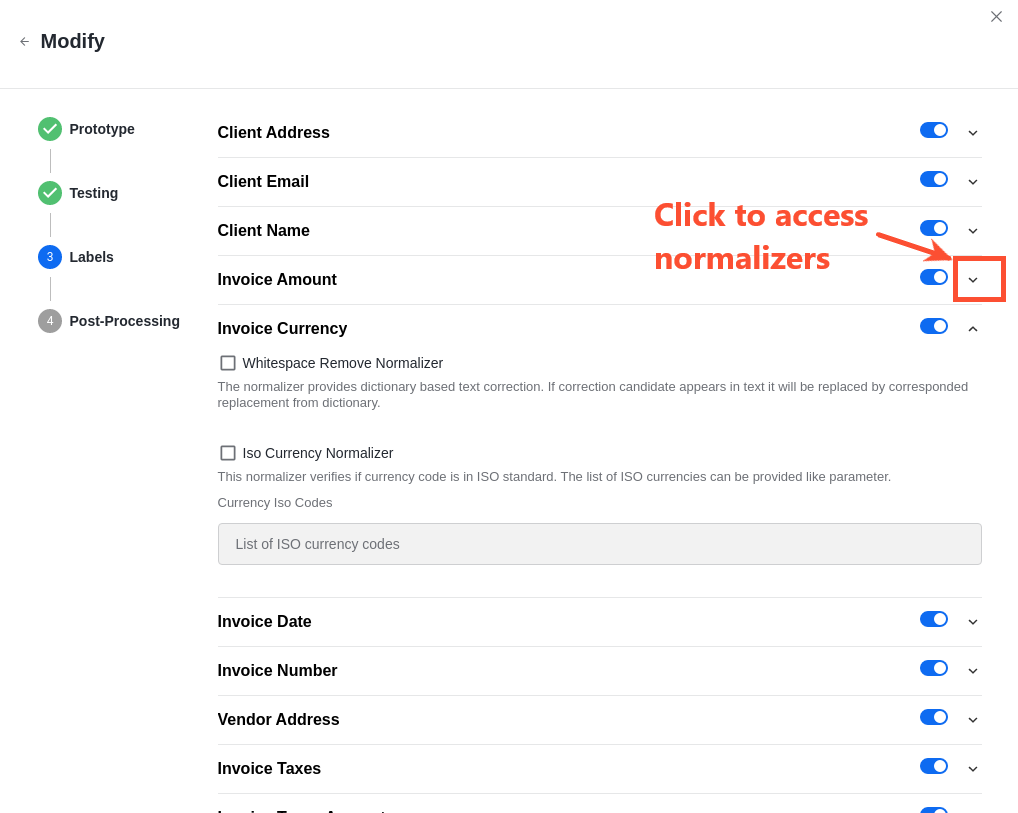
To configure normalizers, click the arrow button next to a specific label and make appropriate changes. The initial normalizer configuration is fetched from the model's pipeline. For a normalizer setup example, refer to the article.
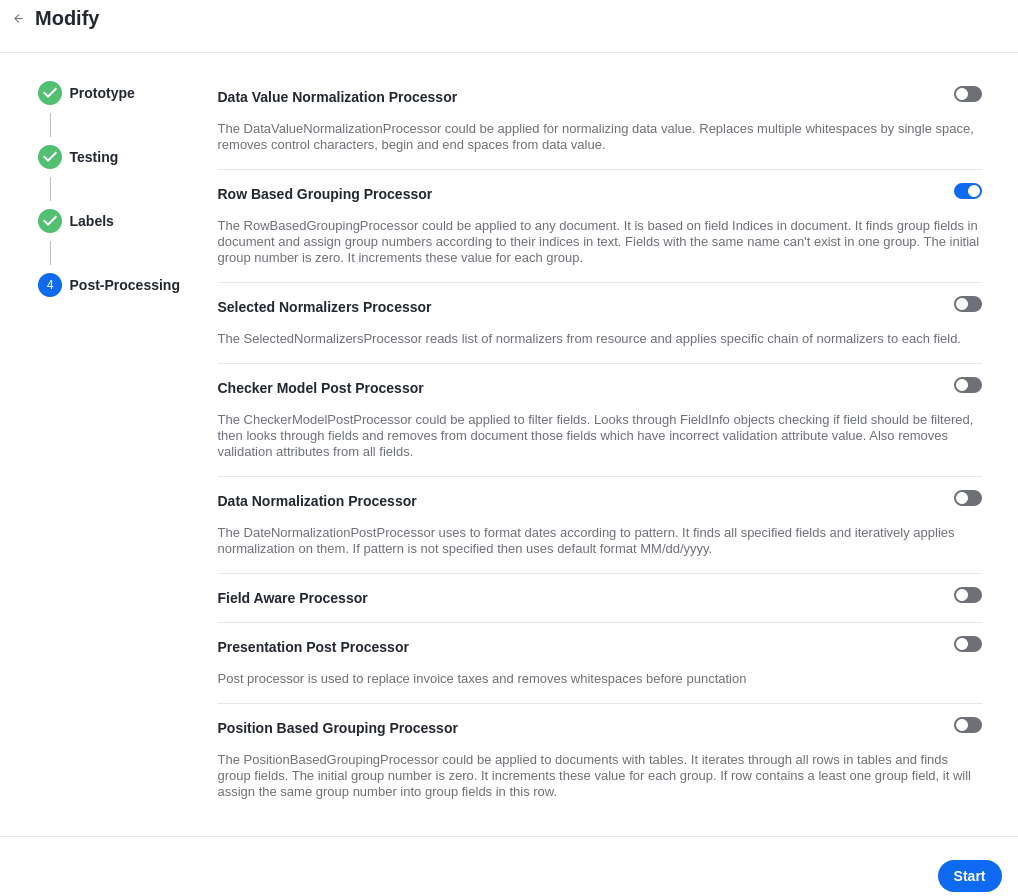
Configure post-processors (if any) by switching the toggles on or off. The displayed list of post-processors is fetched from the prototype model.
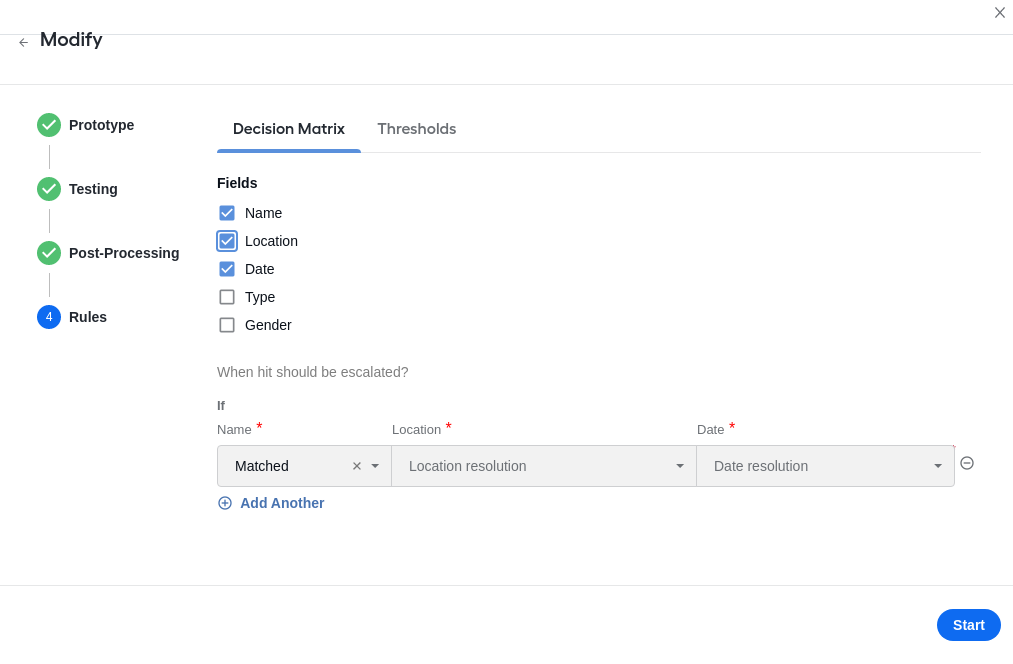
Configure decision rules. They are available if the prototype model contains their definition.
Click Start.
As a result, a new artifact is created, and a test is launched. To find the test, navigate to AutoML > Experiments > Test. Test results are available on the test details page.
Test model
For instructions to set up and run tests and view their results, refer to Run experiments | Tests.
Import model
The flows for importing a model differ depending on whether you have an ML Ops Platform integrated. Integration of the ML Ops Platform allows importing not only WorkFusion models but also external GenAI models.
Import model without ML Ops Platform integrated
With no ML Ops Platform integrated, the capability to import GenAI models is NOT available, so you can import only WorkFusion models.
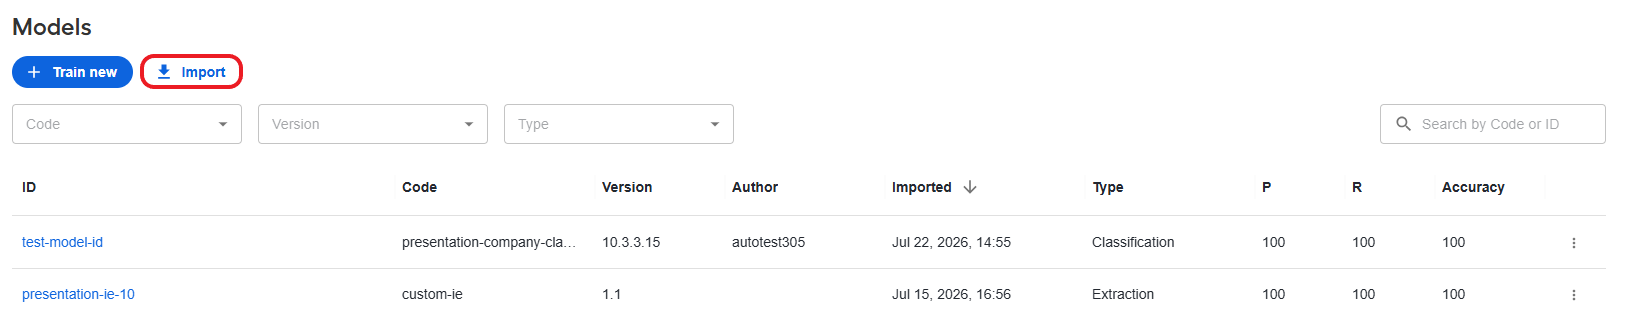
To import a WorkFusion model as a bundle (a zip archive) to your environment, go to the Models page and click Import.
Alternatively, you can import a model bundle via the Pipelines page.
An imported bundle can include only models and pipelines. When the bundle contains any other assets, the import fails.
In case you import models only, associated pipelines must be already deployed to the target environment. Otherwise, the import fails.
The import status is visible above the Models list. The following statuses are possible:
Uploading: the bundle is being uploaded to Control Tower. At the stage, you can stop the procedure by clicking the cross button.

Importing: models and pipelines are being deployed to your environment. At the stage, you can no longer stop the procedure.

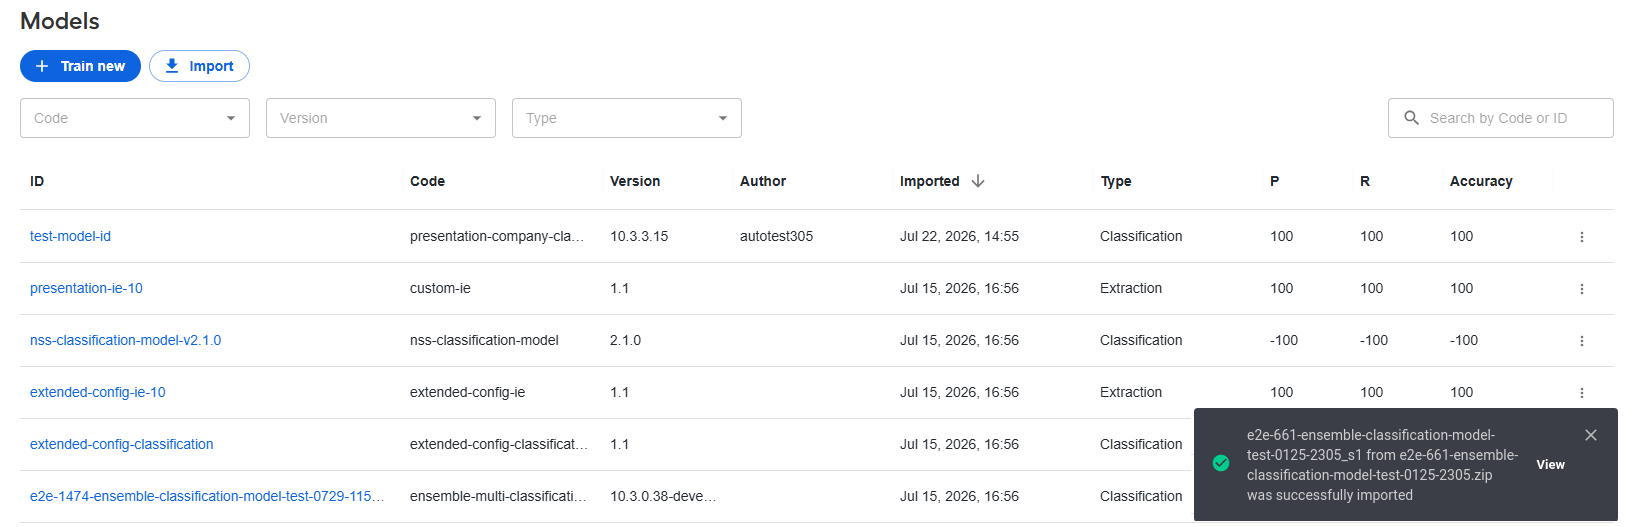
Success: the status appears once the assets from the bundle are moved to the target environment. It disappears automatically after about 15 seconds, or you can click the cross button. To view the bundle details, click View.
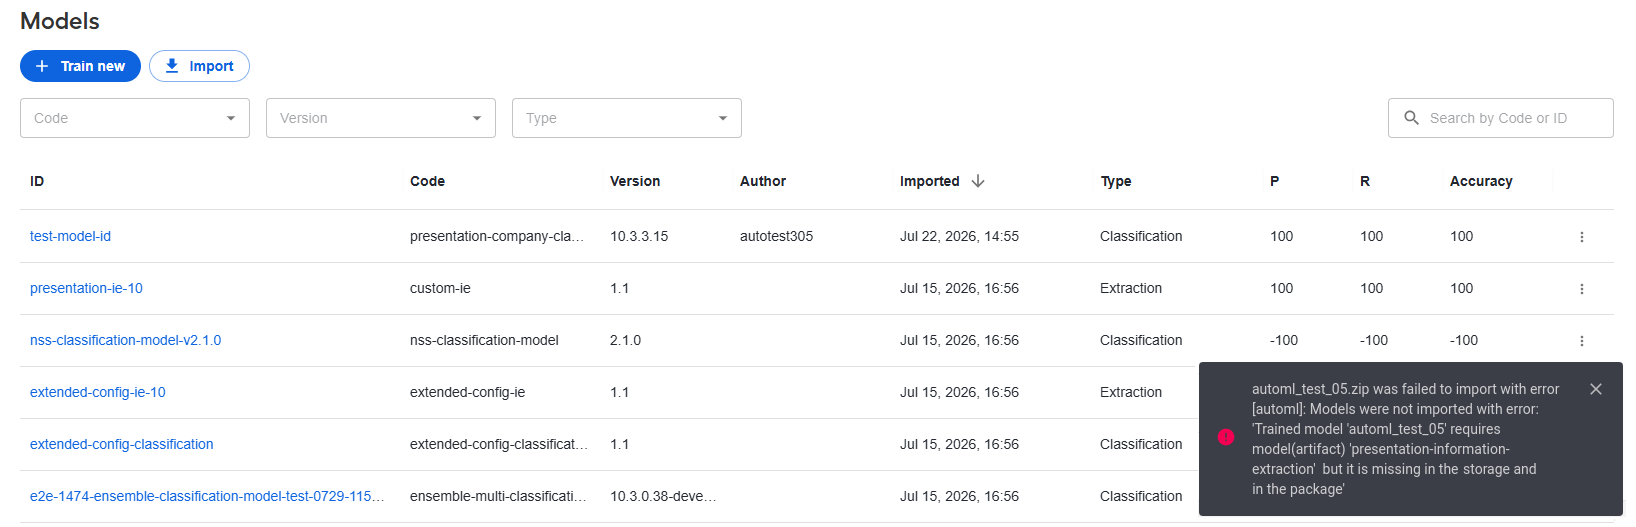
Failed: the status appears for each error. You need to close the messages manually. Those assets that were imported before the error (if any) appear in the Models and Pipelines lists accordingly.
Import model with ML Ops Platform integrated
With the ML Ops Platform integrated, you can import both GenAI and WorkFusion models.
Import WorkFusion model
To import a WorkFusion model with the ML Ops Platform integrated, do as follows:
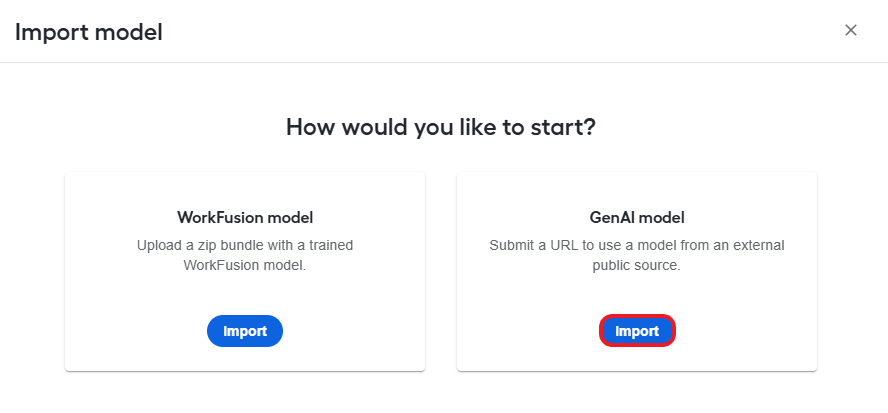
On the Models page, click the Import button.
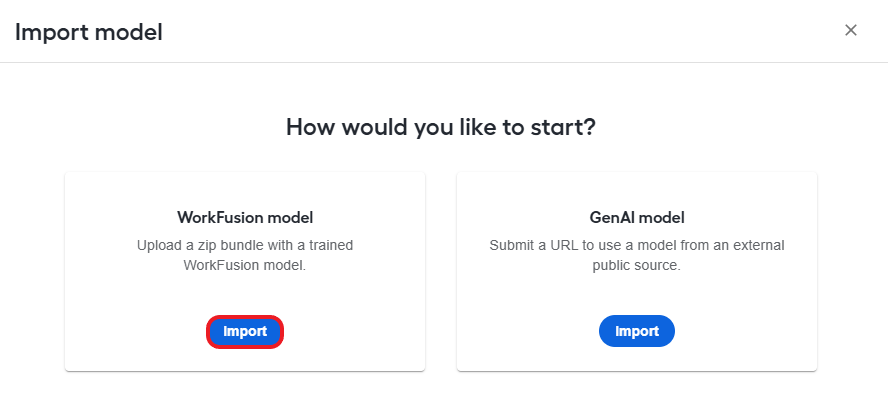
In the displayed popup, click the Import button in the WorkFusion model section.
In the upload dialog, choose a zip bundle with the model and click Open to start the import. For import statuses, see the Import model without ML Ops Platform integrated section.
Alternatively, you can import a WorkFusion model bundle via the Pipelines page.
An imported bundle can include only models and pipelines. When the bundle contains any other assets, the import fails.
In case you import models only, associated pipelines must already be deployed to the target environment. Otherwise, the import fails.
Import GenAI model
To import an external GenAI model, do as follows:
On the Models page, click the Import button.
In the displayed popup, click the Import button in the GenAI model section.
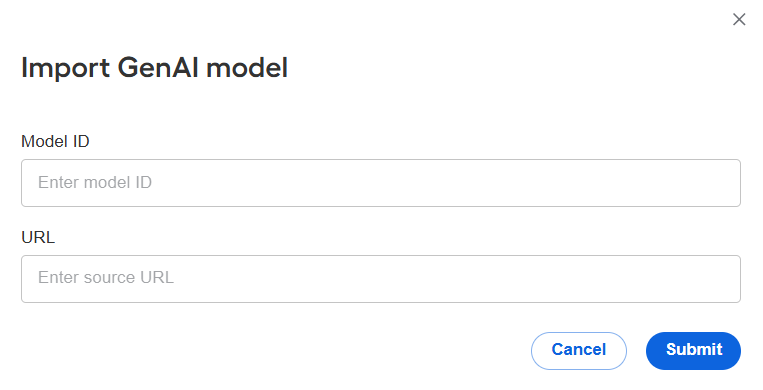
In the Import GenAI model dialog, specify a Model ID and its URL and click Submit.
You are redirected to the screen where you can watch the import progress and status. The statuses are the same as described in the Import model without ML Ops Platform integrated section.
Depending on the imported GenAI model, the import can take up to 20 minutes.
You cannot train, modify, or test imported GenAI models. You can only use them to perform tasks within automation flows. For more information, see Add and configure Model, LLM, and Dataset steps.
Export model
You can export a model as a bundle (a zip archive) in one of the two ways:
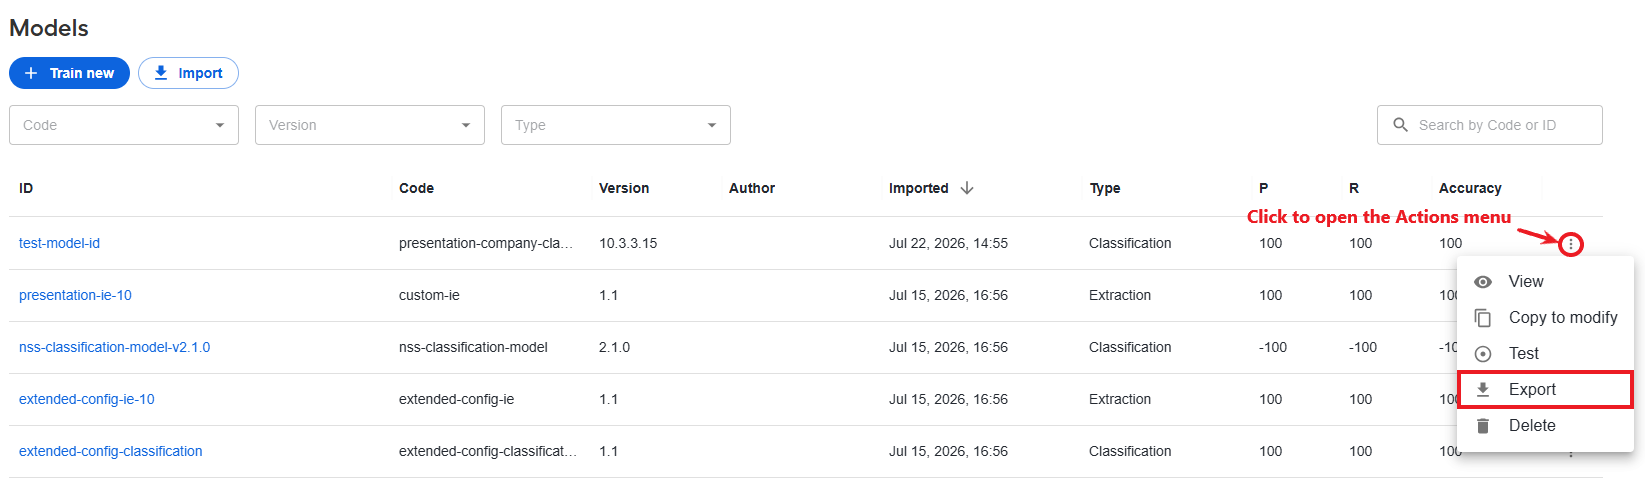
On the Models page, choose a model in the list, open the Actions menu, and select Export.
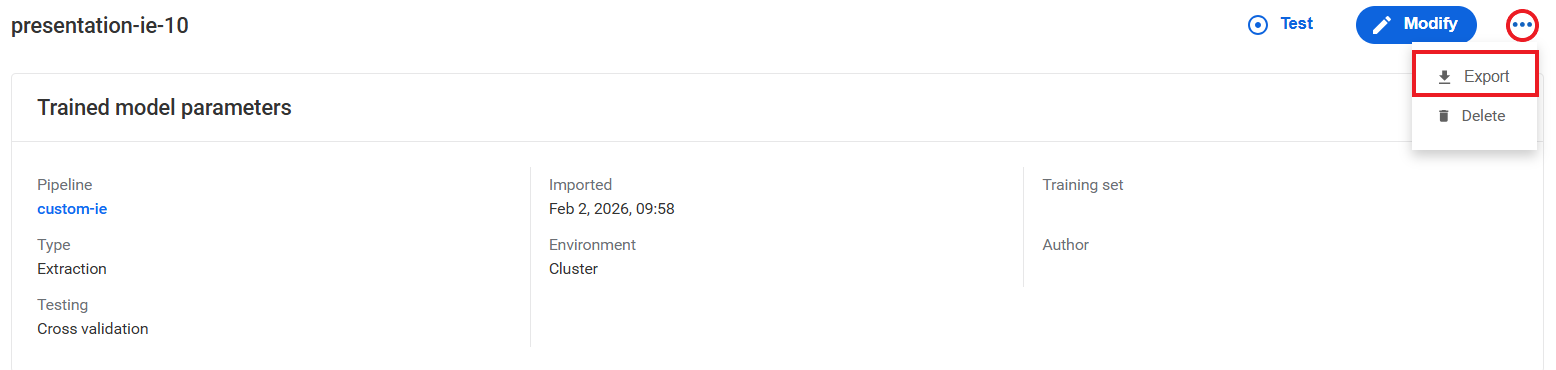
On the model details page, open the Actions menu and click Export.
The resulting zip bundle contains a model (training output) and a pipeline (artifact).
Delete model
You can delete a model in one of the two ways:
On the Models page, choose a model in the list, open the Actions menu, and select Delete.
On the model details page, open the Actions menu and click Delete.
Convert ML Ops-trained models into BEP-compatible
AutoML UI allows you to convert a model that has been trained in the ML Ops platform into one compatible with the Bot Execution Platform (BEP) so that you can test and execute it in Control Tower in an environment where ML Ops is not installed or not available.
You cannot use the conversion feature as a replacement for training. The model must be trained in ML Ops first, then converted after training.
To convert an ML Ops-trained model into a BEP-compatible one, follow the steps below:
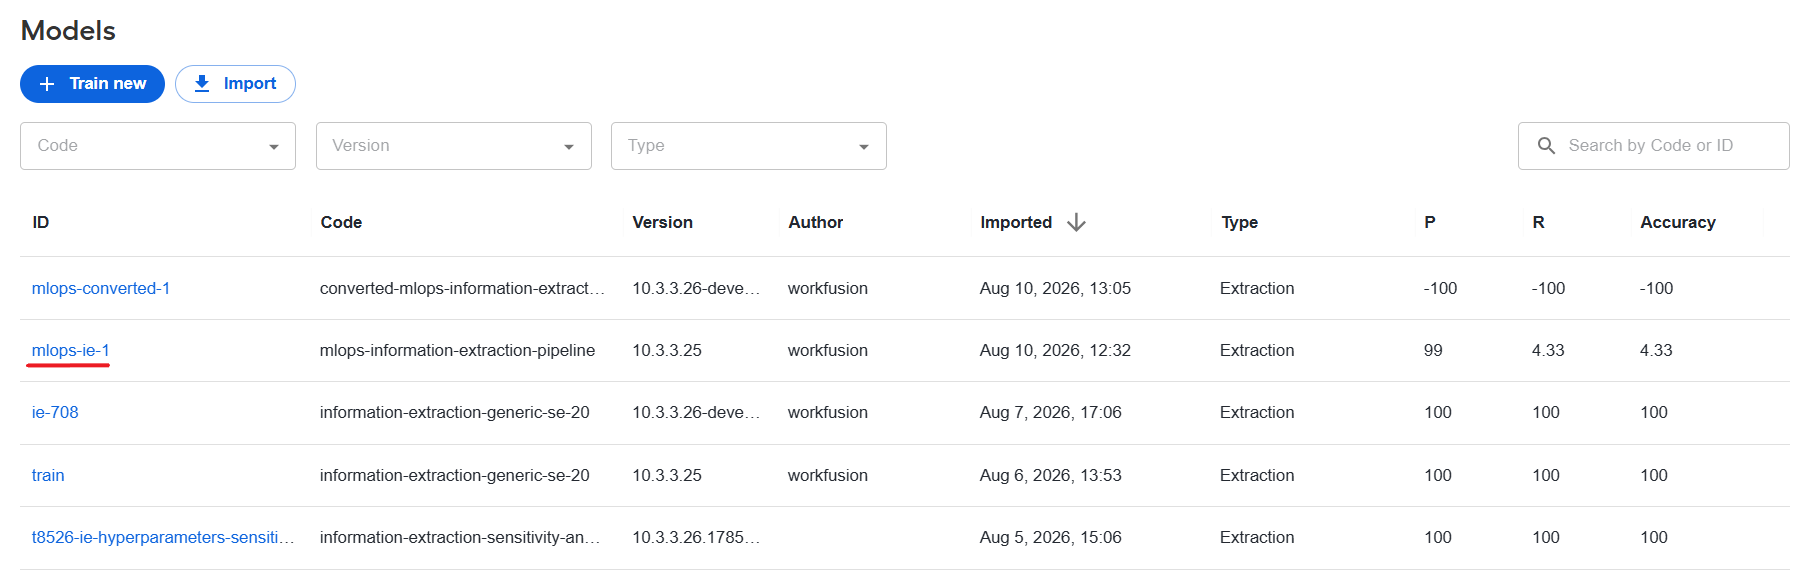
In the Models list, find the ML Ops-trained model you want to convert and click its name to open the model's details page.
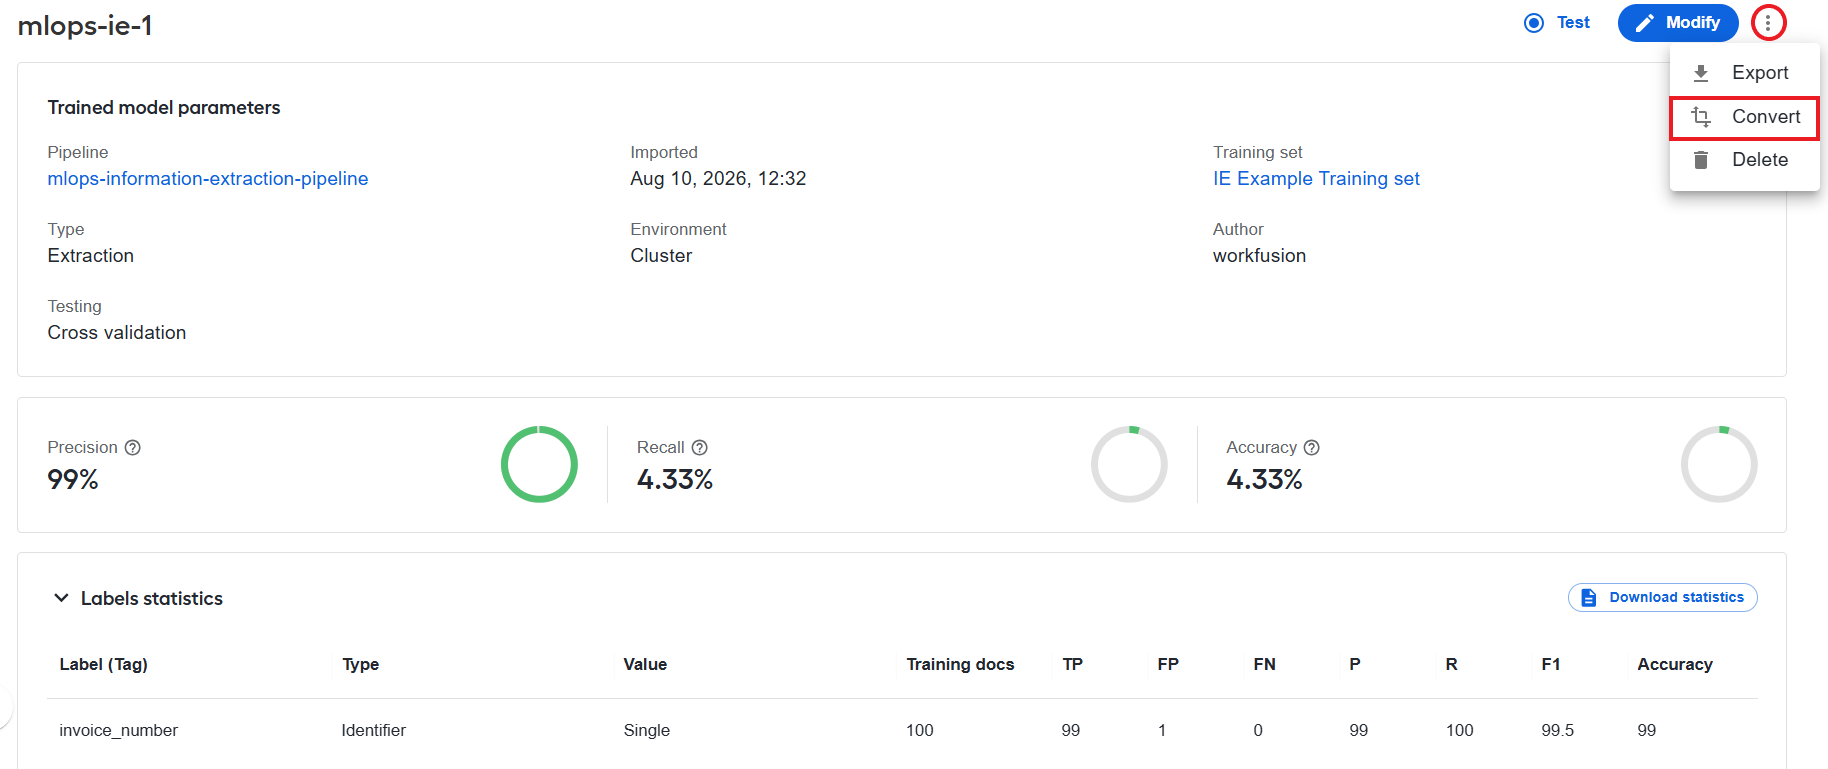
On the model's details page, open the Actions menu and select Convert.
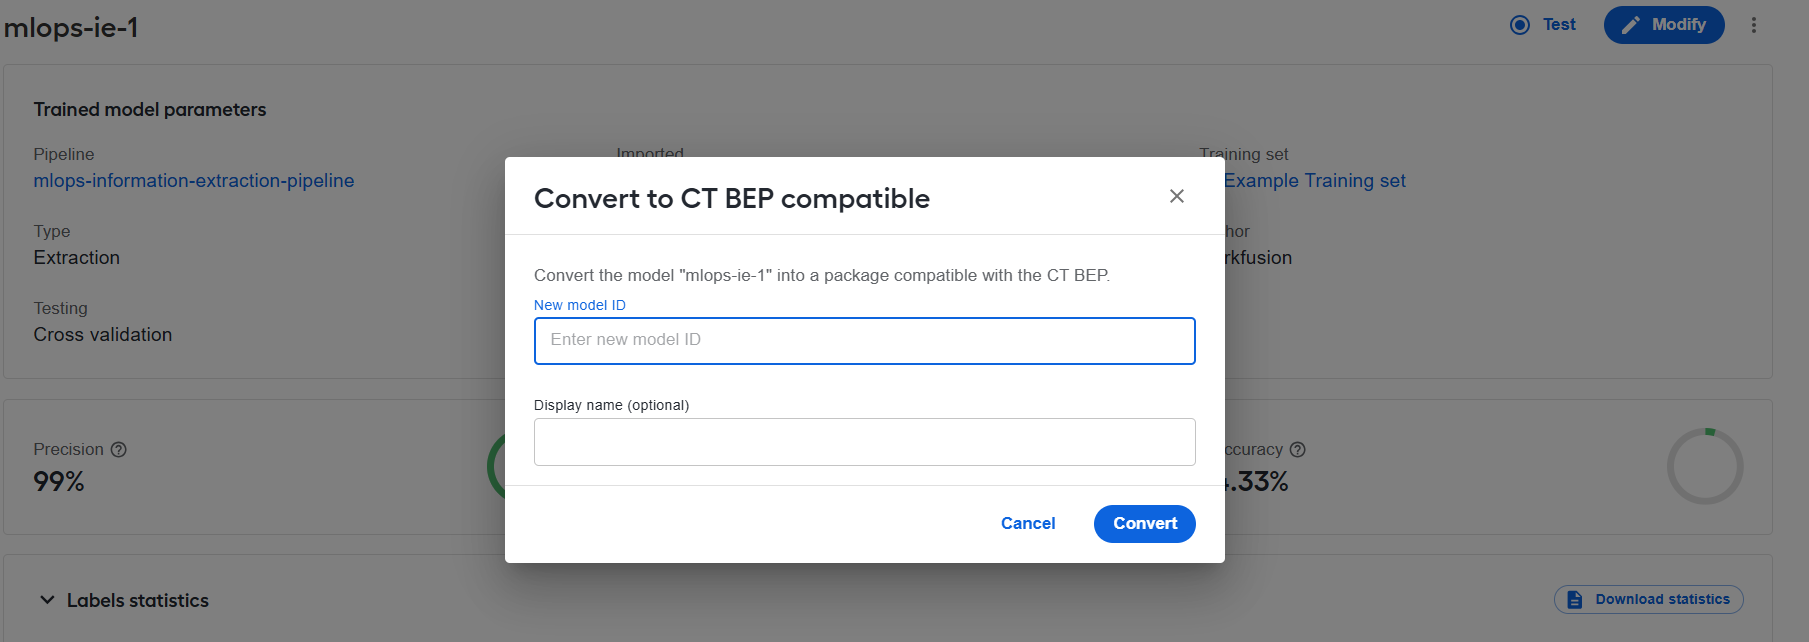
In the displayed popup, specify a model ID and display name (if needed) for the converted model and click Convert.
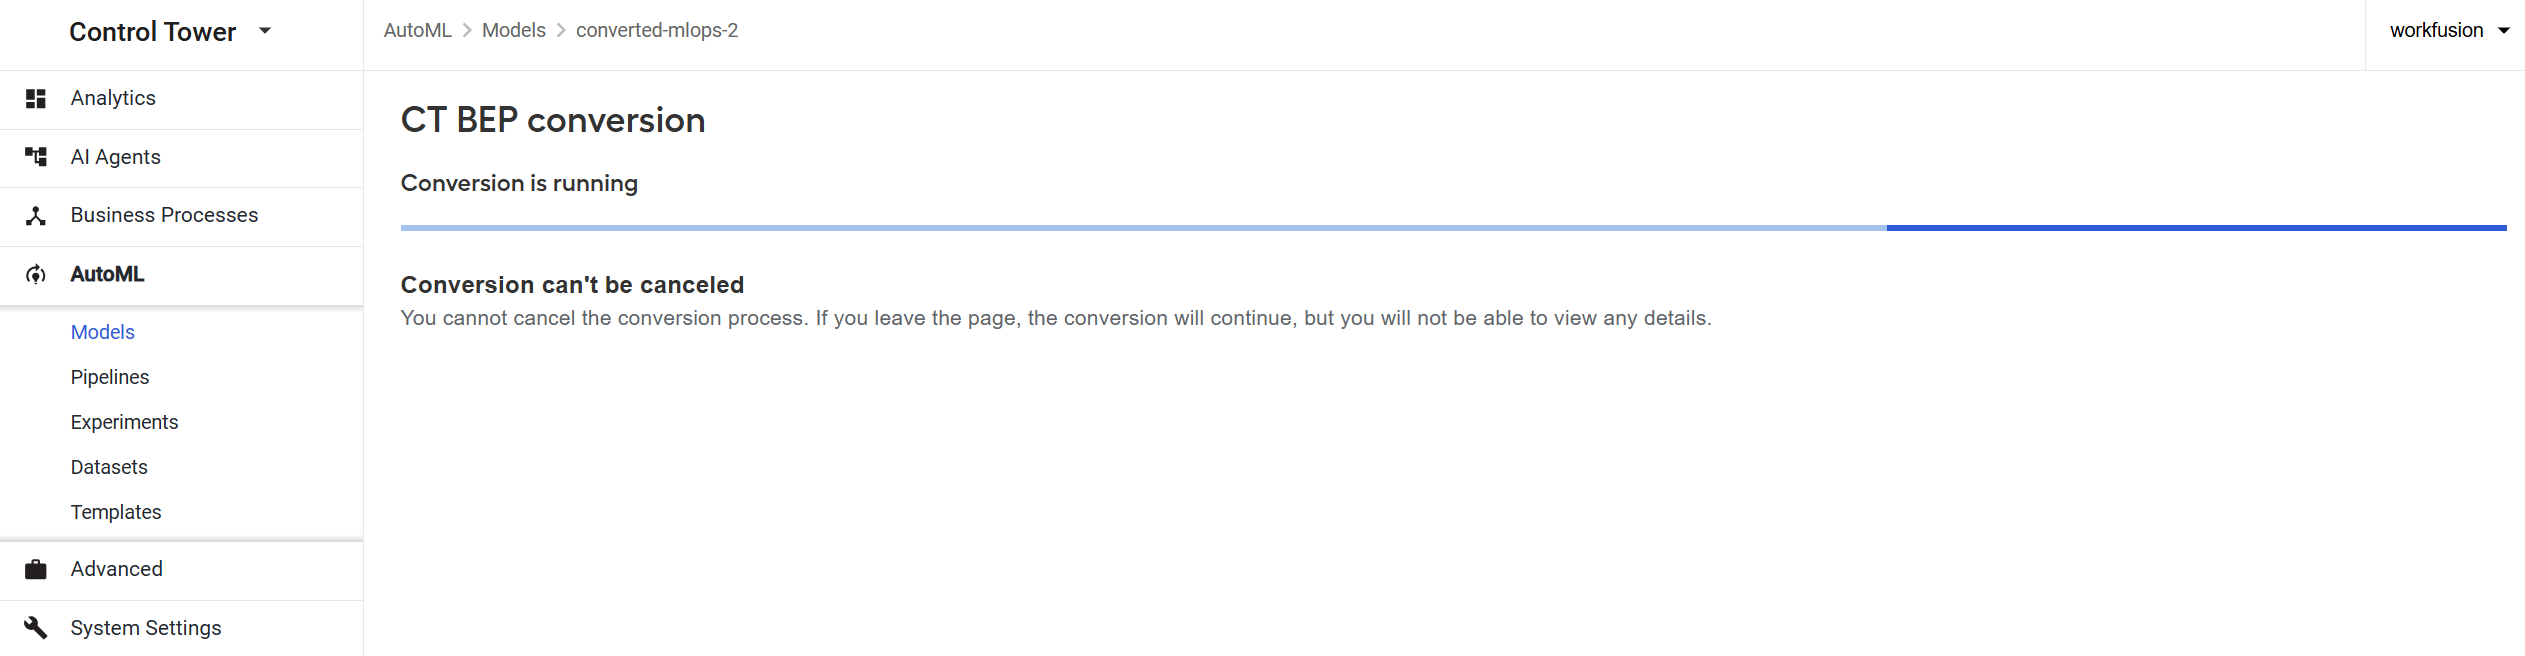
The conversion will start, and you can watch the progress on the screen. The entire conversion process might take up to 10 minutes. You can close the conversion view and continue working elsewhere while the conversion runs in the background.
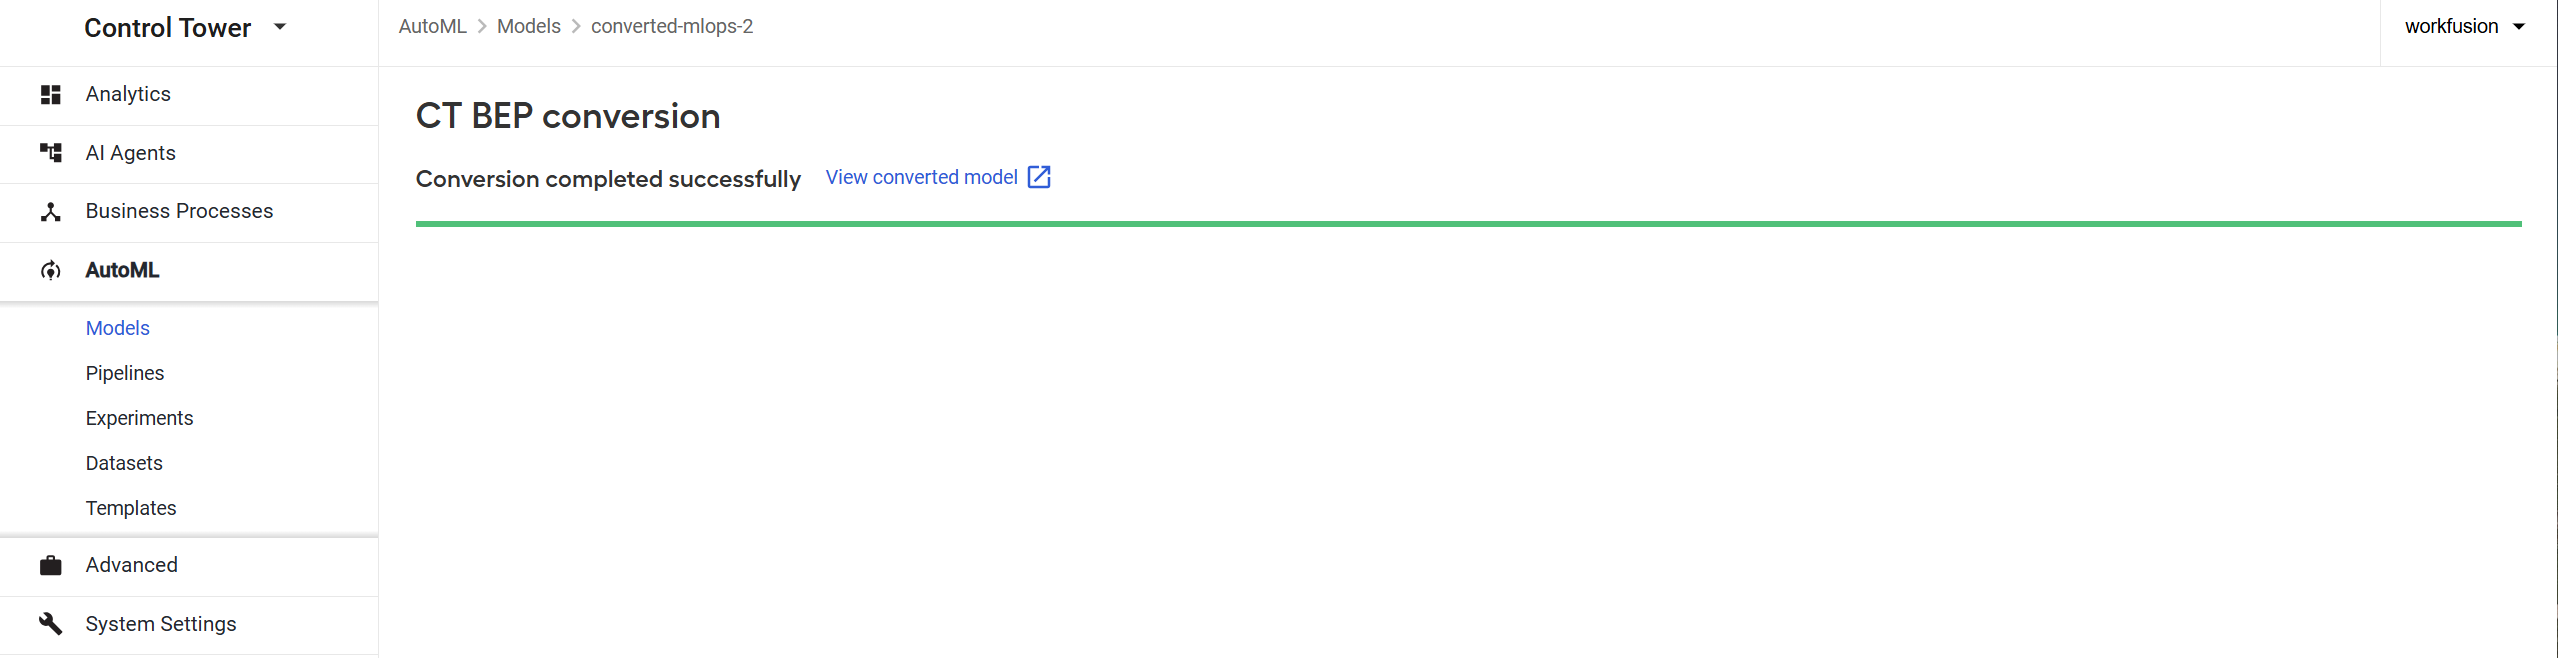
Wait for the conversion to complete. When the conversion is successful, you can see an appropriate message on the conversion progress screen and navigate to the converted model by clicking the View converted model link.
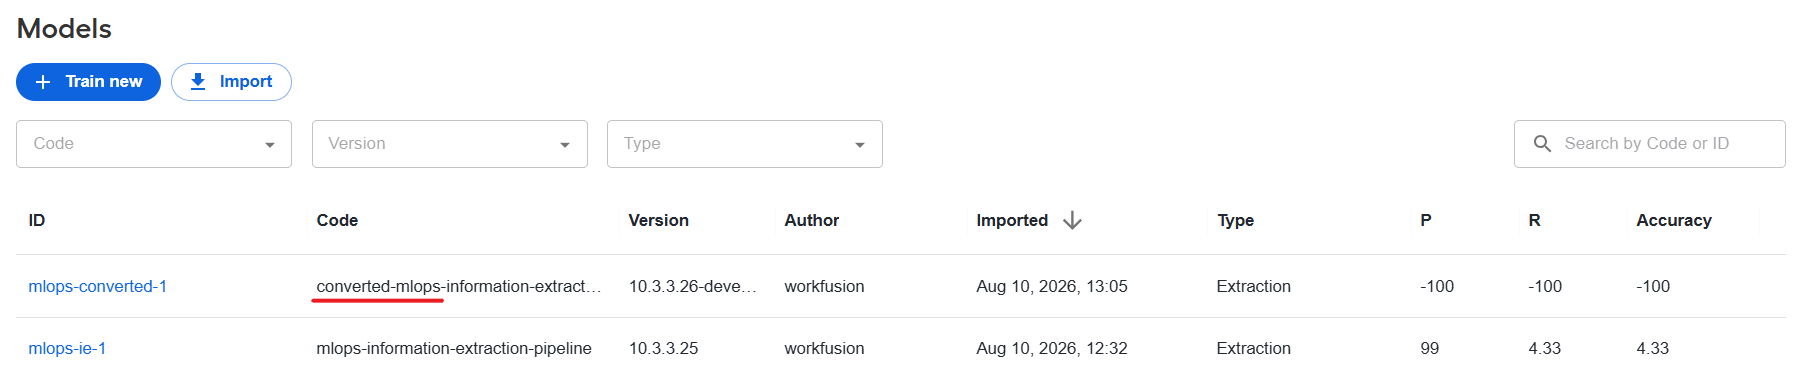
The converted model will also appear in the Models list. You can identify all converted ML Ops models by the converted- pipeline naming pattern (see the Code column in the Models list).